Migration success stories are everywhere. A quick search reveals case studies of companies that moved from Teradata to Snowflake and achieved faster queries, lower total cost of ownership, and happier analysts. Vendors publish them. Consultants reference them. Conference speakers present them as evidence that the migration path is well-trodden and safe.
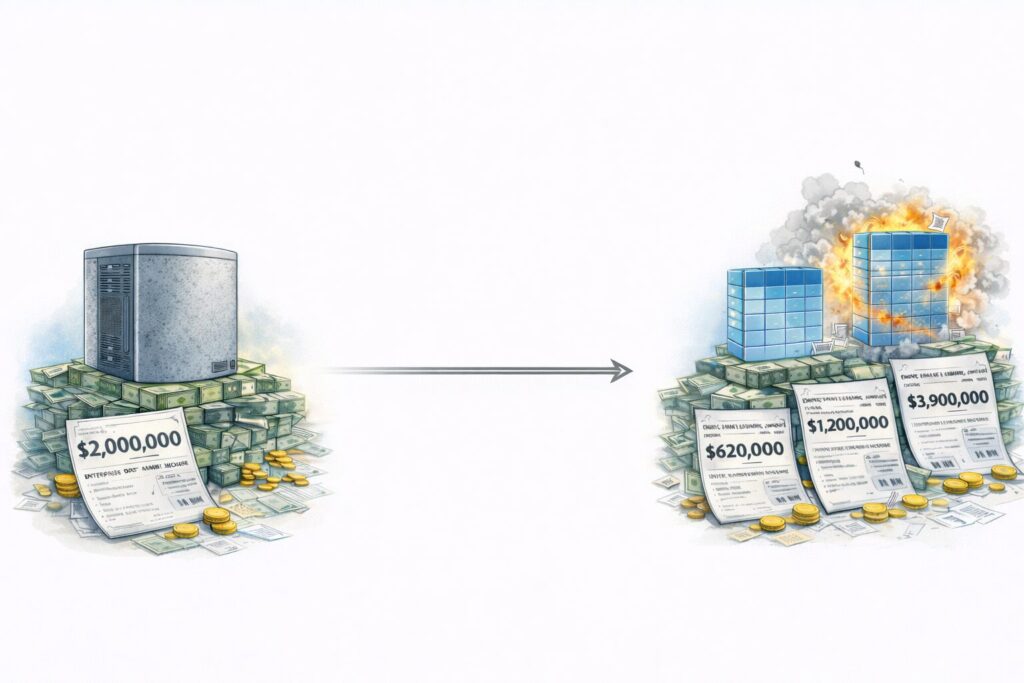
These stories are not necessarily wrong. But they are dangerous, because they create an expectation that is fundamentally misleading: that two organizations with identical Teradata systems, the same indexes, statistics, partitioning, compression, and workload profiles, will achieve the same outcome once they migrate to Snowflake. They will not. Teradata costs also vary by deployment, contract, staffing and operations, even for similar workloads. In Snowflake, identical Teradata source systems can yield a virtually unlimited range of costs depending on how the platform is operated afterward.
Two organizations might end up with bills that differ by single-digit percentages, or by a factor of 2 or more. The outcome is not binary: success or failure. It is a spectrum, and where an organization lands on that spectrum is determined by the operational and behavioral decisions it makes after migration. Schema design, SQL translation quality, and warehouse sizing all matter. But the largest and most unpredictable cost differences come from behavior: how people and systems use the data after it lands in Snowflake.
Migration success stories typically emphasize technical achievements: faster queries, better concurrency, reduced administrative overhead. But cost is the metric most likely to surprise, because it depends most heavily on post-migration behavior.
Two Migrations, One Success, One Failure
The following Company A/B comparison is an illustrative scenario, not a measured customer benchmark. Both migrate 10 TB, but differing runtime, concurrency, refresh and governance choices can change cost.
Company A separates workloads from day one. ETL runs on a dedicated Large warehouse that suspends after 60 seconds of inactivity. Reporting dashboards run on a Small warehouse with aggressive auto-suspend. Ad-hoc analysis runs on a separate X-Small warehouse. Dashboards refresh hourly. Governance, including resource monitors, statement timeouts, and role-based access controls, is in place before the first user connects. Each of these choices is a deliberate cost design decision, not an accident.
Company B creates a single Large warehouse for everything, mirroring its Teradata architecture where all workloads shared one system. Dashboards refresh every 5 minutes. Multiple teams spin up exploratory workloads without coordination. The warehouse rarely suspends because something is always running.
Company B may incur higher costs under these assumptions; quantify the difference from actual metering rather than presuming the outcome. Not because Snowflake charged them unfairly, but because their usage patterns consume far more compute. If Company A publishes a case study, it will read as a resounding success: lower costs than Teradata, faster queries, delighted stakeholders. Company B, reading that same case study, will be bitterly disappointed when their own results look nothing like it. The case study is not lying. It is simply describing a result that is not transferable, because the organizational behaviors that produced it are not part of the story.

Get the complete Teradata tuning book, free
Teradata Query Performance Tuning: The DWHPro Guide
By Roland Wenzlofsky & Artemios Vogiatzis
206 pages on statistics and demographics, access paths and indexes, query execution plans, and joins. Get the full PDF and practical Teradata updates from DWHPro.
Confirm your email to receive your download link. Privacy policy. Unsubscribe in any newsletter.
About the free bookHow Teradata’s Pricing Model Made Query Costs Invisible
Why do teams end up in Company B’s position? Because Teradata’s fixed-capacity model conditioned an entire generation of professionals to think about performance, throughput, and resource contention, not about the cost of individual queries. Running an additional 10,000 queries on a Teradata system usually does not increase the annual expense by a single dollar.
This is not a deficiency of Teradata professionals. It is a rational adaptation to the platform’s economic model. In a system where capacity is purchased upfront, the sensible optimization target is utilization: ensuring that the available resources are used as efficiently as possible. TASM workload rules, AMP Worker Task allocation, and priority scheduling all exist to distribute fixed resources across competing demands. The question was never “what does this query cost?” but rather “does this query fit within the available capacity?”
Traditional fixed-capacity contracts can make some incremental query costs hard to see, but costs and performance do not transfer automatically between organizations. Contract terms, utilization, support and workload details still differ.
Warehouse runtime is billed, but an additional query can add no incremental warehouse charge when it fits existing running capacity or reuses an eligible result. A resume can trigger minimum billing. Model time and service usage rather than assigning a fixed cost to every query.
Where the Cost Divergence Originates
The cost gap between Company A and Company B breaks down across several dimensions, none of which are visible in a traditional capacity-based cost model.
Dashboard Refresh Frequency
In Teradata, refresh frequency was a performance question: can the system handle the additional load without degrading other workloads?
In Snowflake, it is a cost question: is the organization willing to pay for this frequency?
A five-minute refresh produces twelve times as many requests as hourly refresh, not necessarily twelve times the compute charge. Cache reuse, overlapping requests, already-running capacity, suspension and minimum billing determine the difference.
Trust and Re-Run Behavior
When analysts trust the data, they query it once and reuse the results. When trust is low, as in Company B, they re-run queries with slight modifications, add joins to cross-check numbers, and validate results against multiple data slices. This effect is particularly acute in the months immediately after migration. Teams are unfamiliar with the new platform. Numbers look slightly different due to rounding or data type changes. The natural response is to investigate, and investigating means running more queries. In our experience, the post-migration validation phase can temporarily double or even triple the steady-state query volume, and this must be accounted for in any realistic cost forecast.
Warehouse Strategy and Runtime
The total query volume may be similar between Company A and Company B. The total billable warehouse runtime is not. Company A’s three separate warehouses each suspend during their idle periods. Company B’s single warehouse never reaches the auto-suspend threshold because something is always running. This distinction, between query volume and warehouse runtime, is critical and often overlooked. The gap widens further when concurrency triggers multi-cluster scaling. Snowflake’s multi-cluster warehouses (Enterprise Edition) can spin up additional clusters to handle simultaneous users, but each additional cluster multiplies the credit burn rate. If concurrency patterns are not explicitly modeled in the cost forecast, the bill reflects unplanned scaling that no one approved or anticipated.
Why Traditional Cost Estimation Fails
Most Snowflake migration cost estimates model infrastructure costs, including storage volume, warehouse sizes, and credit rates. In many cases, the estimate is further anchored by reference to published success stories: “Company X migrated a similar volume and achieved 40% cost savings.” The implicit assumption is that similar data volumes produce similar costs. In Snowflake, this assumption is false.
What teams should model is behavior: how often queries will run, how many dashboards will refresh, how much re-run and validation will occur, and how quickly new use cases will emerge once the friction of the old platform is removed.
Teradata cost estimation is an engineering exercise: estimate the hardware capacity and licensing tier required to serve the expected workload.
Snowflake cost estimation is a design exercise: predict how the organization will behave on a platform that offers elastic capacity within configured and service limits and charges for every unit of consumption.
We consider a good practice to model Snowflake costs in several scenarios rather than as a single number: a disciplined-usage base case, a realistic moderate case reflecting planned adoption, and an upper-bound case reflecting what happens when adoption accelerates faster than governance. Ranges give leadership the context to make informed trade-offs between cost and governance investment. A single number creates false confidence that erodes trust when the first bill arrives higher than projected.
What Teradata Migration Teams Should Do Differently
Several practices can materially reduce the risk of cost surprises after migration.
The first is to forecast behavior, not infrastructure. Before migration, the team should explicitly document assumptions about query frequency, dashboard refresh rates, concurrent user counts, and expected growth in new use cases. These assumptions are harder to forecast than warehouse sizing, and when they are wrong, the errors tend to be larger. Building monitoring dashboards from day one turns cost management from a monthly surprise into a continuous practice.
The second is to separate workloads and set guardrails from day one. ETL, reporting, and ad-hoc analysis should run on dedicated warehouses with appropriate sizing and auto-suspend settings. Resource monitors, statement timeouts, and role-based access controls should all be configured before the first query executes. Retrofitting governance after organic usage patterns have established themselves is far more difficult and politically costly than building it correctly from the start.
The third is to never use an external success story as a substitute for an internal cost model. Another company’s migration outcome reflects its organizational discipline, governance maturity, and dashboard refresh policies. None of these factors transfers. A cost model built on the organization’s own workload inventory, behavioral assumptions, and governance readiness will always be more accurate than one anchored to a case study from a company with different habits.
The fourth is to model the migration phase separately. Dual-run periods, validation queries, backfills, and reconciliation checks are temporary but expensive. If these costs are not included in the forecast, the first months of Snowflake bills will look alarmingly high compared to the steady-state estimate, and leadership will lose confidence at exactly the wrong moment.
The Mindset Shift
Snowflake can have lower total cost when workload design, usage, contracts and operations support that outcome. Deliberately designing usage patterns can help; carrying habits over unchanged is not an explanation for guaranteed savings.
The next time a vendor, a consultant, or a conference speaker presents a Snowflake migration success story, the correct response is not “we can achieve the same.” The correct response is: “What were the behavioral and organizational decisions that made this outcome possible, and are we prepared to make those same decisions?” Without that question, the success story is useless.
Roland Wenzlofsky is a data warehouse consultant with over 20 years of experience. He is the author of “Teradata SQL Tuning”.
Planning a move? Our Teradata-to-Snowflake migration services include representative workload benchmarks, cost assumptions, and a phased delivery plan.
Planning a Teradata-to-Snowflake migration?
Review the assessment, conversion, reconciliation and cutover work needed for a controlled transition.
Get the complete Teradata tuning book, free
Teradata Query Performance Tuning: The DWHPro Guide
By Roland Wenzlofsky & Artemios Vogiatzis
206 pages on statistics and demographics, access paths and indexes, query execution plans, and joins. Get the full PDF and practical Teradata updates from DWHPro.
Confirm your email to receive your download link. Privacy policy. Unsubscribe in any newsletter.
About the free book