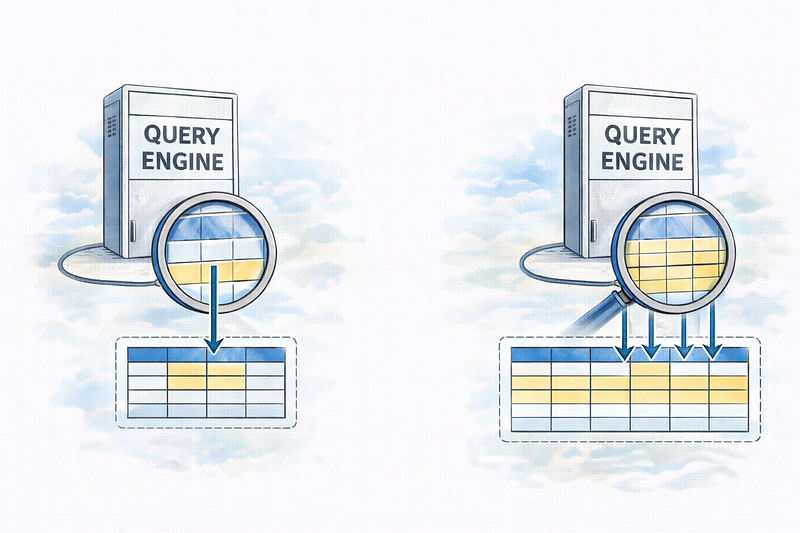
Every data platform eventually faces the same question: how do you serve both the analyst running a full-table scan across billions of rows and the application retrieving a single customer record in milliseconds? The answer shapes the architecture. But increasingly, the answer is not shaped by engineering elegance. It is shaped by survival.
Over the past fifteen years, both Teradata and Snowflake have been forced to expand beyond their core strengths. Not because their original architectures were flawed, but because the market demanded capabilities that neither platform was designed to deliver. The result is a convergence that raises an uncomfortable question: Is architecture driven by market pressure actually good for the customers who depend on these systems?
Where They Started
Teradata built its reputation on a shared-nothing architecture that distributes data across Access Module Processors (AMPs) using a Primary Index. This design serves both analytical and tactical workloads in a single storage format. A unique Primary Index gives you single-AMP access for point lookups. Full-table scans are distributed across all AMPs for analytical processing. One engine, one storage layer, one consistent view of the data. Tactical and strategic workloads coexist on the same hardware, managed through TASM priority rules. For decades, this worked. Teradata dominated the enterprise data warehouse market because the architecture delivered what enterprises needed: reliable, high-performance analytics at scale.
Snowflake entered the market with an entirely different premise. From its founding, Snowflake was designed as a pure analytical platform built for the cloud. Data is stored in immutable, compressed, columnar micro-partitions in cloud object storage. This architecture excels at analytical scans: the columnar format enables efficient compression, column pruning, and partition elimination. There are no row-level indexes, no row-level locking, and no enforced referential integrity. These are not shortcomings. They are deliberate consequences of an architecture optimized for OLAP and nothing else. And for its intended purpose, Snowflake’s design was exceptional.
Both platforms were strong within their design boundaries. The trouble began when the market started pushing both of them outside those boundaries.
The Cloud Hype and Teradata’s Response
The rise of cloud computing changed the rules of the data warehouse market almost overnight. Suddenly, the ability to scale compute and storage independently, to provision resources in seconds, and to pay only for what you use became table stakes. Snowflake, BigQuery, and Databricks all offered elastic, cloud-native architectures that resonated with a market eager to move away from on-premises infrastructure.
Teradata’s traditional shared-nothing cluster, while excellent for performance, cannot scale compute and storage independently. Adding capacity meant adding nodes. Scaling required planning, procurement, and often downtime. The architecture that made Teradata powerful for decades became, in the eyes of the market, a liability.
Teradata had to respond, and the response was VantageCloud Lake. The architecture connects the traditional shared-nothing Primary Cluster with one or more elastic Compute Clusters that access an Object File System (OFS) sitting on cloud object storage.
The primary cluster supports traditional block storage and can access OFS under supported configurations. Independent compute clusters have different storage and operation capabilities; verify the deployed release rather than equating the primary cluster only with BFS.
The Compute Clusters access data in the Object File System. These clusters scale elastically and independently, just as the market demanded. They are designed for analytical workloads: large scans, aggregations, and data science processing. However, OFS tables lack Primary Index access, secondary indexes, join indexes, and several other features that Teradata professionals have relied on for decades.
The result is a hybrid architecture. The traditional engine remains at the core, now surrounded by cloud-native components that address the market’s demand for elasticity. Whether this combination delivers the best of both worlds or introduces complexity that neither architecture had on its own is a question each customer must answer for themselves.
Snowflake’s Forced Expansion into Tactical Workloads
Snowflake faces pressure from the opposite direction. As Snowflake became the center of the modern data stack, customers began asking it to handle workloads it was never designed for. Application state management, real-time serving layers, operational dashboards requiring low-latency lookups whose end-to-end timing must be measured: these are transactional patterns, and Snowflake’s columnar, immutable micro-partition architecture is fundamentally unsuited to them.
For years, the standard answer was to use an external transactional database alongside Snowflake, with pipelines moving data between the two. This worked, but it meant maintaining two platforms, two skill sets, and accepting latency between the transactional and analytical views of the same data. Customers wanted consolidation.
Hybrid row-store indexes support point access, while a columnar representation supports analytical access. End-to-end latency depends on workload, compute, contention and network; sub-millisecond response is not guaranteed.
The query engine is shared. The same virtual warehouses execute queries against both standard and hybrid tables. You can join them in a single query, within a single transaction, without federation. The optimizer decides whether to read from the row store or the columnar copy based on the query pattern.
Hybrid-table restrictions and quotas change. The current official restrictions describe database-cloning support, so a blanket “no cloning” claim is incorrect. Verify supported clone scope, streams, ingestion, sharing, region and quota requirements for the intended workflow.
Snowflake had to add transactional capabilities because the market demanded it. Whether bolting a row store onto a columnar analytical engine yields an architecture that genuinely serves transactional workloads well, or creates a compromise that serves neither pattern optimally, is again a question each customer must evaluate honestly.
The Convergence Nobody Planned
Step back, and the pattern is unmistakable.
Teradata started with a single-tier architecture optimized for both workloads and added cloud object storage to survive the cloud era. Snowflake started with a cloud-native architecture optimized for analytics and added a row store to address transactional demands. Both ended up with a two-tier storage model where the core decision is the same: does this table need low-latency point access, or is it primarily scanned analytically?
Teradata BFS and OFS are alternative storage placements; a table in one tier is not thereby stored simultaneously in both. Snowflake hybrid tables maintain row and columnar representations. Those are different physical designs, even though both require workload-aware choices.
And both architectures introduce a data placement decision that did not exist before. Teradata administrators must decide which tables belong on the Primary Cluster versus OFS. Snowflake users must decide which tables justify the overhead of hybrid table storage. Get this decision wrong, and you pay a penalty: either in performance or in operational complexity.
This convergence was not driven by a shared engineering vision. It was driven by market pressure. Teradata had to offer cloud elasticity or risk losing customers to cloud-native competitors. Snowflake had to offer transactional capabilities or risk losing workloads to platforms that could handle both. Neither vendor set out to build a two-tier architecture. Both were pushed into it.
Should We Be Comfortable with This?
Here, we step back from the technical analysis and share an honest observation. We are not sure if this dynamic is good.
The claim that competitive survival drove these designs is my interpretation, not an established causal finding. Whether their tradeoffs help a customer requires workload, operational and reliability evidence.
Similarly, a pure Snowflake deployment did not require its users to think about row stores, consistency windows, or request-based billing for individual table reads. Hybrid tables ask users to manage a fundamentally different storage tier within a platform that was built around a single, elegant abstraction. That is also a new complexity.
We are not saying these developments are wrong. Market pressure is a legitimate force, and both vendors are responding to real customer needs. Teradata customers genuinely needed cloud elasticity. Snowflake customers genuinely needed tactical query capabilities. But there is a difference between a feature that emerges from deep architectural conviction and a feature that emerges from the need to check a competitive box.
The history of enterprise software is full of examples where market-driven feature additions created products that were broader but not deeper. Platforms that tried to be everything to everyone often ended up serving no one as well as they served their original audience. Whether Teradata’s cloud extensions and Snowflake’s transactional additions will prove to be genuine architectural advances or competitive compromises is something only time will tell.
What This Means for Practitioners
For data professionals working with either platform, the practical takeaway is straightforward: understand the original design intent of your platform, and be cautious about using features that were added under market pressure rather than born from the architecture.
If you are on Snowflake, hybrid tables solve a genuine problem for lightweight transactional use cases. But they are not a replacement for the analytical architecture that makes Snowflake effective. Do not assume that hybrid tables will behave like standard Snowflake tables just because they share the same query engine.
In my view, the architecture raises useful long-term reliability questions. Actual reliability requires operational and failure evidence; this opinion does not supersede representative benchmarks or recovery tests.
The market dynamics of the last fifteen years have been extraordinary. They have pushed two very different platforms toward a remarkably similar architectural shape. Whether that shape is the future of data management or simply the byproduct of competitive survival remains an open question. One we think is worth asking honestly.
Roland Wenzlofsky is the author of “Teradata SQL Tuning” and co-author of the upcoming “Teradata to Snowflake: Avoiding the Traps.” He is the founder of DWHPro LLC and has over 20 years of experience in data warehouse performance optimization
Written by Roland Wenzlofsky, founder of DWHPro and author of Teradata Query Performance Tuning. DWHPro has helped data warehouse practitioners for 15+ years.
Deciding what to change in your data platform?
Compare optimisation, modernisation and migration against your workload and business requirements.