Memory access is generally faster than storage access, but end-to-end database performance depends on the workload and execution design. This article describes historical Teradata 14.10 Intelligent Memory and spinning-disk concepts.
There is a significant difference in access times between memory and hard disks or solid-state drives (SSD), and this disparity has always existed and will persist.
The 80/20 access pattern is a heuristic, not a universal workload property. Measure the actual working set before choosing how much data to retain in memory; no product guarantees the fastest access for every query.
Teradata categorizes data by its access frequency into cold, warm, hot, and very hot. This classification system is known as Teradata Intelligent Memory.
Teradata categorizes data by its access frequency
Feature availability and configuration must be checked for the deployed release and platform; the historical 14.10 discussion does not establish support in every configuration.

Get the complete Teradata tuning book, free
Teradata Query Performance Tuning: The DWHPro Guide
By Roland Wenzlofsky & Artemios Vogiatzis
206 pages on statistics and demographics, access paths and indexes, query execution plans, and joins. Get the full PDF and practical Teradata updates from DWHPro.
Confirm your email to receive your download link. Privacy policy. Unsubscribe in any newsletter.
About the free bookUnderstanding the principles of “data temperature” and its correlation with storage type requires knowledge of the data storage mechanisms employed in a Teradata system.
Teradata AMPs must have data blocks in memory before operating on rows. As a result, each AMP has its own FSG cache. In Teradata 14.10 and beyond, AMPs have supplementary memory for frequently accessed data. Blocks of data transferred to this memory are potentially retained for several days.
Teradata AMPs must have data blocks in memory
If solid-state drives are an option, they would be the optimal choice due to their superior speed compared to traditional hard disks.
A physical disk has tracks, heads and rotations; these should not be conflated with Teradata logical cylinders.
Teradata cylinders are logical groups of sectors containing data blocks. Cylinder Read can reduce I/O operations, but reading a logical cylinder is not equivalent to one physical disk rotation.
Data blocks are stored in cylinders, and a full cylinder can be read into memory with one spin
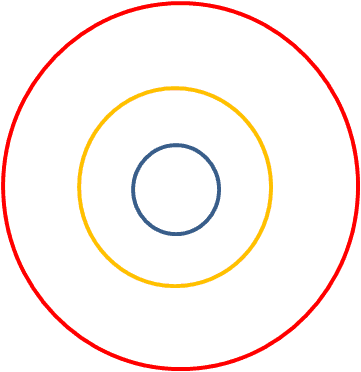
Historical temperature-based placement descriptions concern particular storage configurations; they do not imply fixed inner/outer physical-cylinder placement on SSD or cloud storage.
Teradata’s memory strategy follows a hierarchy, taking into account the position of different cylinders. The hierarchy includes memory, SSD, and disks.
Evaluate the memory and storage hierarchy against actual cost, capacity and workload measurements; this historical discussion is not a product performance ranking.
Deciding what to change in your data platform?
Compare optimisation, modernisation and migration against your workload and business requirements.
Get the complete Teradata tuning book, free
Teradata Query Performance Tuning: The DWHPro Guide
By Roland Wenzlofsky & Artemios Vogiatzis
206 pages on statistics and demographics, access paths and indexes, query execution plans, and joins. Get the full PDF and practical Teradata updates from DWHPro.
Confirm your email to receive your download link. Privacy policy. Unsubscribe in any newsletter.
About the free book
I have some basic questions.
if you can help that will be really helpful.
Question 1
Memory used by AMP
Vdisks
Ram
Spool Space
FSG Cache
Please confirm
Question 2
Is FSG Cache memory is same as Spool space where data is moved when Joins takes Place
Question 3
Each AMP has its own RAM, So Ram is not FSG Cache memory. Its memory is fixed in AMP or it is also decided by PDE as same is done for FSG
Question 4
Initially, Data is distributed across AMPs so where we store this data on . is its Vdisk or Pdisks. Vdisk is a combination of Pdisks ?
Question 5
If Possible can please someone provides an image for what inside an AMP?
That’s more like catching up with multi-temperature data management that DB2 10.1 has introduced in 2012 already.
Now DB2 with BLU is again a step further it offers true in-memory capability as SAP HANA does. In-memory is more than just storing the records in RAM. It is also about applying intelligent features to reduce the data volume that has to keep in memory resp. pushed through the execution pipelines of the CPUs. That’s why data skipping, columnar storage and sort-order preserving compression algorithms like Huffmann encoding (IBM calls it “actionable compression) and SIMD processing play a critical role in true in-memory databases. Unfortunately, Teradata is not yet there.