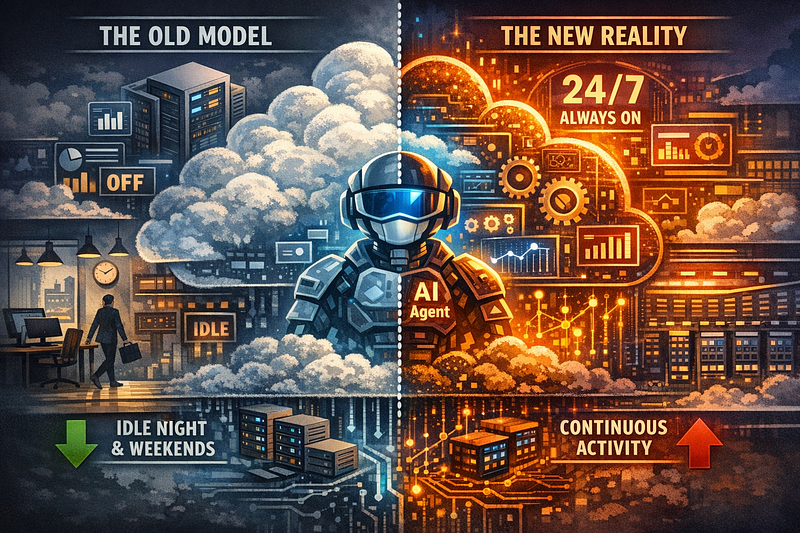
I have spent over twenty years building and optimising enterprise data warehouses, and in that time, I have watched the industry cycle through several dominant narratives. The current one is elasticity. Cloud databases are sold on a simple promise: compute can suspend when idle, scale back up when needed, and spare you the cost of owning fixed capacity around the clock. Warehouses auto-suspend and auto-resume. Some platforms offer both on-demand and capacity-based models. Others allow capacity to be paused to save costs.
That pricing story made sense when workloads were mostly human-shaped: analysts active during the day, ETL windows at night, quieter weekends, and plenty of idle time in between. In that world, idle-elimination features could produce meaningful savings.
But that narrative assumes the system is idle often enough for scale-to-zero savings to matter; elasticity can still help variable peaks and concurrency. And AI agents are pushing data platforms in exactly the opposite direction.
The old assumption: bursty workloads
Most cloud migration business cases quietly rely on one economic assumption: workloads are bursty. Some jobs spike hard, but they do not run continuously. This is exactly where pay-per-use models shine.
What is rarely mentioned in those business cases is that even cloud vendors position capacity commitments as beneficial for steady-state workloads, which implies the standard elastic model is not always the cheapest choice once utilisation becomes stable.
That nuance matters. The phrase “you only pay when you use it” describes one end of the pricing spectrum, not the entire cloud pricing landscape. Major platforms already support reservations, commitments, and capacity-oriented purchasing models alongside pure usage pricing.
In my experience, the elasticity argument is strongest in pre-production environments, development clusters, and seasonal workloads. It is weakest in mature production environments where the system is busy most of the time anyway. This is precisely the scenario that AI agents are creating.
What changes when agents arrive
Once autonomous agents begin running continuously against a data platform, idle windows shrink.
That can mean agents monitoring data quality, checking anomalies, generating SQL through semantic layers, querying structured and unstructured sources, refreshing feature stores, running background investigations, or servicing natural-language requests from business users across time zones. Cloud-native AI agents are already designed to plan tasks, use tools, and analyse both structured and unstructured data sources — and they do so without waiting for someone to open a dashboard.
This does not mean every deployment becomes saturated around the clock overnight. But it does mean the probability of persistent background activity rises sharply. A warehouse that used to sleep between user sessions now wakes up more often, suspends less often, and may spend much more time at sustained utilisation. And warehouses continue consuming credits while running, regardless of whether a human initiated the query.
At that point, the economic advantage of pure pay-per-use pricing becomes weaker. If utilisation is consistently high and predictable, reservations, commitments, or owned capacity can become more attractive. Cloud platforms already recommend capacity commitments for steady-state workloads, and some now offer capacity reservations for 1-year terms at significant discounts compared to pay-as-you-go rates.
This is not a universal rule. Sometimes, cloud still wins because of hardware efficiency, operations, concurrency, or contract terms. But the direction is clear: the more continuously the system runs, the less value you get from “scale to zero.”
The second problem: cost opacity
Agents do not just reduce idle time. They also change cost visibility.
With human-driven workloads, organisations usually have a rough mental model of spend: how many analysts they have, when the dashboards run, when ETL starts, and what the month-end surge looks like. Agents introduce a more opaque pattern. They decide what steps to take, which tools to call, how often to retry, and how broadly to explore — without asking for permission first.
The fact that cloud vendors are now building dedicated governance layers specifically for AI agents and LLM endpoints is itself an acknowledgment that these workloads need specialised control. If agents behaved like ordinary reporting jobs, there would be no need for separate monitoring.
To be fair, runaway cost is not unique to agents. Poorly governed BI, bad ETL design, and uncontrolled ad hoc workloads have been generating ugly cloud bills for years. I have seen this in almost every large environment I have worked in. But agents amplify the problem because they operate more continuously, make more decisions without human review, and can execute at a cadence that exceeds normal human query patterns. That is why vendors are now adding AI-specific monitoring and controls rather than treating these workloads like ordinary compute.
The evidence is already showing up in budgets
Broader AI spending does not measure database-agent costs. Without a named survey, publication date, sample and methodology, the former budget percentages and dollar figures cannot support this argument and are omitted. Measure agent-attributed queries, tokens and service charges in your own environment.
The argument here is a workload scenario: more continuous agent activity may reduce idle periods. It is not a measured forecast of adoption, return on investment or database spending.
Anyone who has managed a large data warehouse knows this feeling. It is the same dynamic that played out when self-service BI tools arrived, and suddenly every analyst could launch expensive queries without going through a DBA. The difference with agents is that they do not go home at 18:00.
Why does this strengthen the on-prem argument
In an agent-heavy environment, fixed-capacity systems start to look different.
On-premise platforms do not magically become cheaper in every case. They still carry software, support, power, cooling, and administrative costs. But they do offer something; cloud consumption models often struggle to provide boundedness under continuous load. Once capacity is bought and installed, the short-run infrastructure cost of an additional query is often low until the system reaches its throughput limits.
The question then becomes less “what will this query cost?” and more “can the platform absorb this workload mix without hurting service levels?” That is a shift that favours platforms with mature workload governance.
I know this territory well. Workload management frameworks on mature on-premise platforms support workload throttles, system throttles, concurrency controls, and delay or reject behaviour when a system gets busy. Throttles reduce resource contention by delaying or rejecting work once thresholds are exceeded. These capabilities have been refined over decades and are well documented. In an agent-saturated world, they do not become less relevant — they become more relevant. When additional work is cheap to launch but expensive to let run unchecked, governance becomes part of the value proposition.
Cloud vendors are already adapting
Cloud vendors can see this shift, too, and they are responding.
Distinguish budget alerts from enforceable limits. For example, Snowflake Resource Monitors can suspend covered warehouse usage, but do not cap every serverless service; budgets and alerts need separate response policies. Confirm the exact AI gateway or agent-service controls, scope and enforcement delays before relying on a spending ceiling.
These are meaningful additions. But they also reveal something important: once you need specialised budgets, monitoring, rate limits, capacity controls, and agent-specific billing views, you are already moving away from the clean simplicity of the original elasticity narrative. The cloud model is not disappearing. But it is becoming more governed, more contractual, and more capacity-like, which is precisely what it was supposed to replace.
The real reframing
This is the part most migration business cases still avoid.
If AI agents materially increase the frequency of workloads and reduce idle time, the central economic question changes. The comparison is no longer just “elastic cloud versus fixed on-prem.” It becomes something more nuanced: cost predictability, throughput governance, and bounded spending on one side — operational flexibility and outsourced infrastructure on the other.
That is a very different discussion from the one most organisations had when they signed their cloud migration contracts.
It is not a death sentence for cloud databases. It is a warning that the old sales story was built around a workload shape that AI agents may steadily erode. The more your platform behaves like an always-on system, the less persuasive “pay only for what you use” becomes — because you are using it all the time.
Roland Wenzlofsky is the founder of DWHPro, a Vienna-based enterprise data warehousing consultancy. He is a Teradata Certified Master with over twenty years of experience across European banking, insurance, and telecom, and the author of “Teradata Query Performance Tuning.” DWHPro provides vendor-neutral advice across Teradata, Snowflake, and Databricks.
Written by Roland Wenzlofsky, founder of DWHPro and author of Teradata Query Performance Tuning. DWHPro has helped data warehouse practitioners for 15+ years.
Deciding what to change in your data platform?
Compare optimisation, modernisation and migration against your workload and business requirements.