There is a question that is almost never asked in the data platform debate, and the reason it is not asked is that nobody benefits from the answer.
The question is this: if every modern platform can load, transform, and make clean data available to users, why does it matter which one we use?
The user opening a dashboard does not care whether the data sits in Teradata block storage or in Parquet files on Amazon S3. The user does not care whether the slowly changing dimension logic was implemented in BTEQ or in PySpark. The user does not care how file compaction works, how deltas are detected, or how the platform records recovery and table changes; Teradata permanent journaling is distinct from its transient journal and write-ahead logging, and Delta’s transaction log serves its own table-management role.
The user cares about one thing: correct numbers, delivered on time, every morning.
Every platform on the market — Teradata, Databricks, Snowflake, BigQuery, Microsoft Fabric — can deliver this. The fundamental purpose of a data warehouse has not changed since the concept was formalised in the early 1990s: ingest raw data, apply business rules, produce clean tables for analytical consumption. The patterns have evolved. Batch ETL gave way to ELT. Real-time streaming entered the picture. Schema-on-read and data mesh became topics of discussion at conferences. But the job the business is paying for remains identical.
And yet, companies are spending millions to replace one platform with another. The consultancies are busy. The vendors are delighted. The conference circuit is thriving. But nobody seems to pause and ask: Are we solving the right problem?
In my experience — and I write this after more than 20 years of building and tuning data warehouses, most of that time on Teradata, with increasing work on Snowflake and now Databricks — the answer, in the majority of cases, is no.
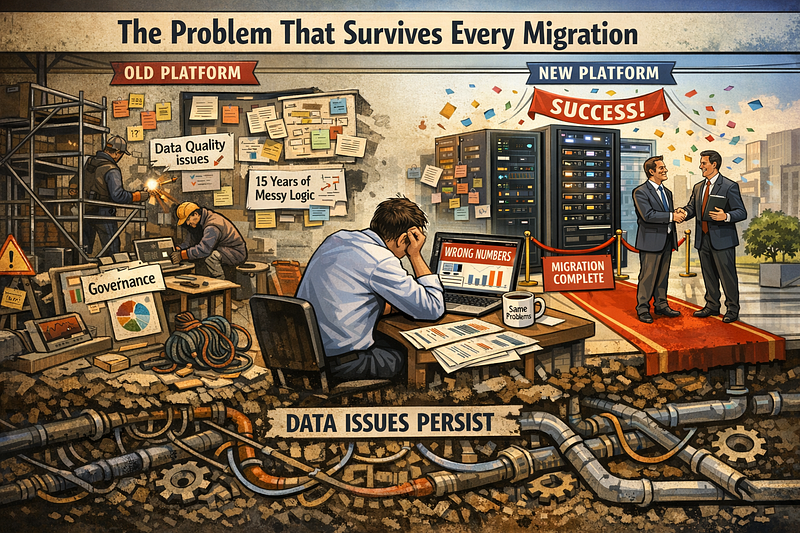
The Problem That Survives Every Migration
Here is the observation that no vendor will put on a slide, no consultancy will lead with in a proposal, and no conference keynote will dedicate more than thirty seconds to:
The biggest problem in most data warehouse environments is not the platform. It is data quality.
It has inconsistent business rules. It is unclear who owns the data. It is governance that exists in a PowerPoint deck but not in practice. It is 2000 source-to-target mappings that have accumulated over 15 years, each with slightly different interpretations of what constitutes an “active customer.” It is the transformation logic that nobody fully understands because the person who wrote it left the company in 2017.
I have seen companies migrate from Teradata to Snowflake and discover, during reconciliation testing, that the numbers on the new platform do not match those on the old platform. Not because the migration was flawed. Because nobody had ever checked whether the old numbers were correct in the first place. They were not. They had not been correct for years. Nobody had noticed because nobody had ever validated from scratch.
This is not an isolated case. In my experience, it is the norm.
A platform migration does not fix data quality. It does not reconcile business rules. It does not create ownership where none existed. What a platform migration does — and this is its one genuine contribution to data quality — is make these problems visible. The reconciliation effort forces teams to look at the transformation logic they have not examined in a decade.
That is valuable. But it is not a reason to migrate. It is a reason to audit your data architecture, regardless of which platform it runs on.
Governance Is Not a Checkbox
When I speak of governance, I do not mean the compliance section in a project charter. I mean the ability to answer, at any moment, questions such as:
Who owns the definition of “revenue” in this organisation — and is that definition applied consistently across every pipeline, every report, and every data product that references it?
When a source system changes a field format at 2 AM on a Saturday, who is responsible for detecting the change, assessing its impact, and propagating the correction through every downstream dependency?
Can the number in the board report be traced, step by step, back through every transformation to the source record — and can someone explain why it is what it is?
If these questions cannot be answered on the current platform, they will not be answerable on the new one either. The platform does not create governance. People create governance. The platform is, at best, a tool that supports them in doing so. At worst, it is a distraction from the fact that nobody is doing the work.
Architecture First. Tools Second.
The order matters. Before any platform evaluation begins, the data architecture must be assessed. Not the technology architecture — the data architecture. The business rules, data flows, quality controls, and lineage.
This means auditing the business rules. Are they documented? Are they consistent across pipelines? Or do three different ETL jobs contain three different definitions of the same metric, each producing a slightly different number?
This means documenting the data lineage. Can any report number be traced back to its source? If this cannot be done on Teradata, it will not be possible on Databricks either — unless it is deliberately designed into the migration, which adds months of work that most migration timelines do not account for.
This means validating the numbers. Running the same business question against the data warehouse and against a manual extract from the source system. If the results do not match, the organisation has a data quality problem that no platform change will resolve.
These problems are platform-independent. They must be addressed first. If the architecture is sound, any modern platform will serve the organisation well. If it is not, no platform will compensate for it.
When the Platform Genuinely Matters
None of the above should be read as an argument that all platforms are interchangeable. They are not. There are legitimate reasons to change platforms. But these reasons are fewer than the industry would have us believe, and they deserve honest examination.
The Talent Pool
This is the most consequential factor and the one discussed least honestly.
If an organisation employs 15 experienced Teradata developers and zero Spark engineers, migrating to Databricks does not merely change the technology. It requires new platform skills, while SQL, domain knowledge, modeling and architectural judgment remain transferable. The pipeline still performs the same function. But nobody knows how to diagnose it when it fails at three in the morning.
Talent availability and training requirements vary by region and role. Verify current Teradata certification/accreditation offerings and local hiring evidence; a universal decline in incoming talent is not established here.
This is not a commentary on the quality of the technology. It is a demographic reality that forces technology decisions regardless of whether the business case supports them.
In my experience, this single factor drives more platform migrations than any technical requirement.
The Ecosystem Beyond ETL
The core data pipeline — ingest, transform, serve — is identical across platforms. But modern analytical work extends beyond the pipeline.
Data science, machine learning, real-time streaming, and the processing of semi-structured and unstructured data are workloads that a traditional data warehouse was not originally designed for. If an organisation requires nothing more than clean data for BI reports and regulatory submissions, Teradata delivers this superbly. It has done so for decades. The SQL optimiser is mature, the workload management is battle-tested, and the platform’s reliability in regulated European environments is difficult to match.
But the moment the business requires model training on warehouse data, the situation changes. Teradata Vantage offers in-database analytics — the SCRIPT table operator for running Python and R in the database, and QueryGrid for federating queries to external systems. These capabilities exist, and they function. But in practice, they are limited in scope and operationally cumbersome compared to a platform like Databricks, where data science is a first-class citizen: notebooks, MLflow, GPU clusters, and the training data coexist in a single environment.
Whether this matters depends entirely on whether the organisation genuinely performs data science, or merely discusses it in board presentations. In my observation, the number of companies that truly need a unified analytics and machine learning platform is considerably smaller than the number of companies purchasing one. But for those who do, the productivity difference is substantial.
The Real Cost of Migration
Migration cost includes licenses, parallel operation, testing, reconciliation, retraining and cutover risk. Their relative size and the duration of dual running are project-dependent; 12–18 months is an illustrative planning scenario, not a universal rule.
And it is the human cost. Senior engineers who have spent 15 years mastering a platform are informed that their expertise is now obsolete. Some will retrain. Some will not. Some will leave during the migration, taking with them institutional knowledge that was never documented and cannot be replaced. I have observed this more than once. The impact on the project is severe and is almost never accounted for in the migration business case.
A credible migration schedule follows from scope, dependencies, data quality and acceptance criteria. Six months may be feasible for some scopes and unrealistic for others.
Vendor Lock-In — In Both Directions
Lock-in differs by object type and surrounding services. Native Snowflake micro-partitions are not directly read by arbitrary external engines, while supported Iceberg tables offer open-format interoperability. APIs, SQL extensions and operational dependencies can still create switching costs on every platform.
The industry narrative suggests that open file formats such as Parquet and Delta Lake make the Lakehouse architecture easier to leave. In theory, this is correct. In practice, the cost of rewriting 5,000 notebooks is not materially different from rewriting 5,000 BTEQ scripts. Lock-in is not principally about file formats. It is about the intellectual property embedded in transformation logic, the operational procedures a team has built over the years, and the institutional knowledge that exists only in engineers’ minds.
But the argument must be made in the other direction as well: remaining on a legacy platform is its own form of lock-in. When the vendor’s roadmap diverges from the organisation’s needs, when support contracts become extortionate, when every new capability requires an expensive upgrade cycle, when integration with modern tools grows increasingly painful — staying can be as costly as leaving. The question is not “migrate or stay.” The question is: which form of lock-in would serve the organisation better over the next five years?
The Honest Assessment
I run a consultancy that helps organisations with data platform architecture and migrations. That is precisely why I can say, with some authority, when a migration is not needed.
The organisations that genuinely benefit from a platform change are those where the current platform cannot support real, funded, and urgent new business requirements — not aspirational ones. Where the talent situation has deteriorated to the point where it constitutes a staffing risk — not a hypothetical concern, but an actual inability to hire or retain. Where the commercial terms have become genuinely untenable. Where the vendor’s roadmap has diverged so far from the organisation’s direction that every project becomes a fight against the platform rather than a use of it.
Everything else — and I include a considerable portion of the migration projects currently underway across European and US enterprises — is vendor-driven anxiety, analyst-driven hype, and consultancies generating revenue from complexity.
I say this as someone who runs a consultancy. The best advice I have given to clients, on more than one occasion, is: do not migrate. Fix your architecture instead.
The One Thing That Matters
The data pipeline does not care what engine runs it. Teradata, Databricks, Snowflake — they are all capable tools in the hands of competent engineers.
In my consulting experience, data quality, business rules, governance and expertise often dominate outcomes. Platform capability, reliability, compatibility and cost can also cause failure; architecture decisions still need evidence.
Get those right, and the platform becomes a detail. Get those wrong, and no migration on earth will save you.
I would be interested to hear from those who have been through a migration: did it solve the problems you expected it to solve? Or did the same problems simply reappear on the new platform?
Roland Wenzlofsky is the founder of DWHPro, a Vienna-based data warehouse engineering consultancy. He is a Teradata Certified Master with over 20 years of experience in enterprise data warehousing across the European banking, insurance, and telecom sectors. He is the author of “Teradata Query Performance Tuning” and writes about the reality of data engineering at www.dwhpro.com.
Written by Roland Wenzlofsky, founder of DWHPro and author of Teradata Query Performance Tuning. DWHPro has helped data warehouse practitioners for 15+ years.
Planning a Teradata-to-Snowflake migration?
Review the assessment, conversion, reconciliation and cutover work needed for a controlled transition.