
A passing test means the tested assertion held for those cases, not that the whole program is correct. This limitation applies to deterministic software as well as systems containing LLMs.
Traditional software tests establish behavior for tested cases, not general correctness. Deterministic programs can silently calculate wrong values. Property-based, randomized and concurrency tests can check invariants without requiring one exact output for every run.
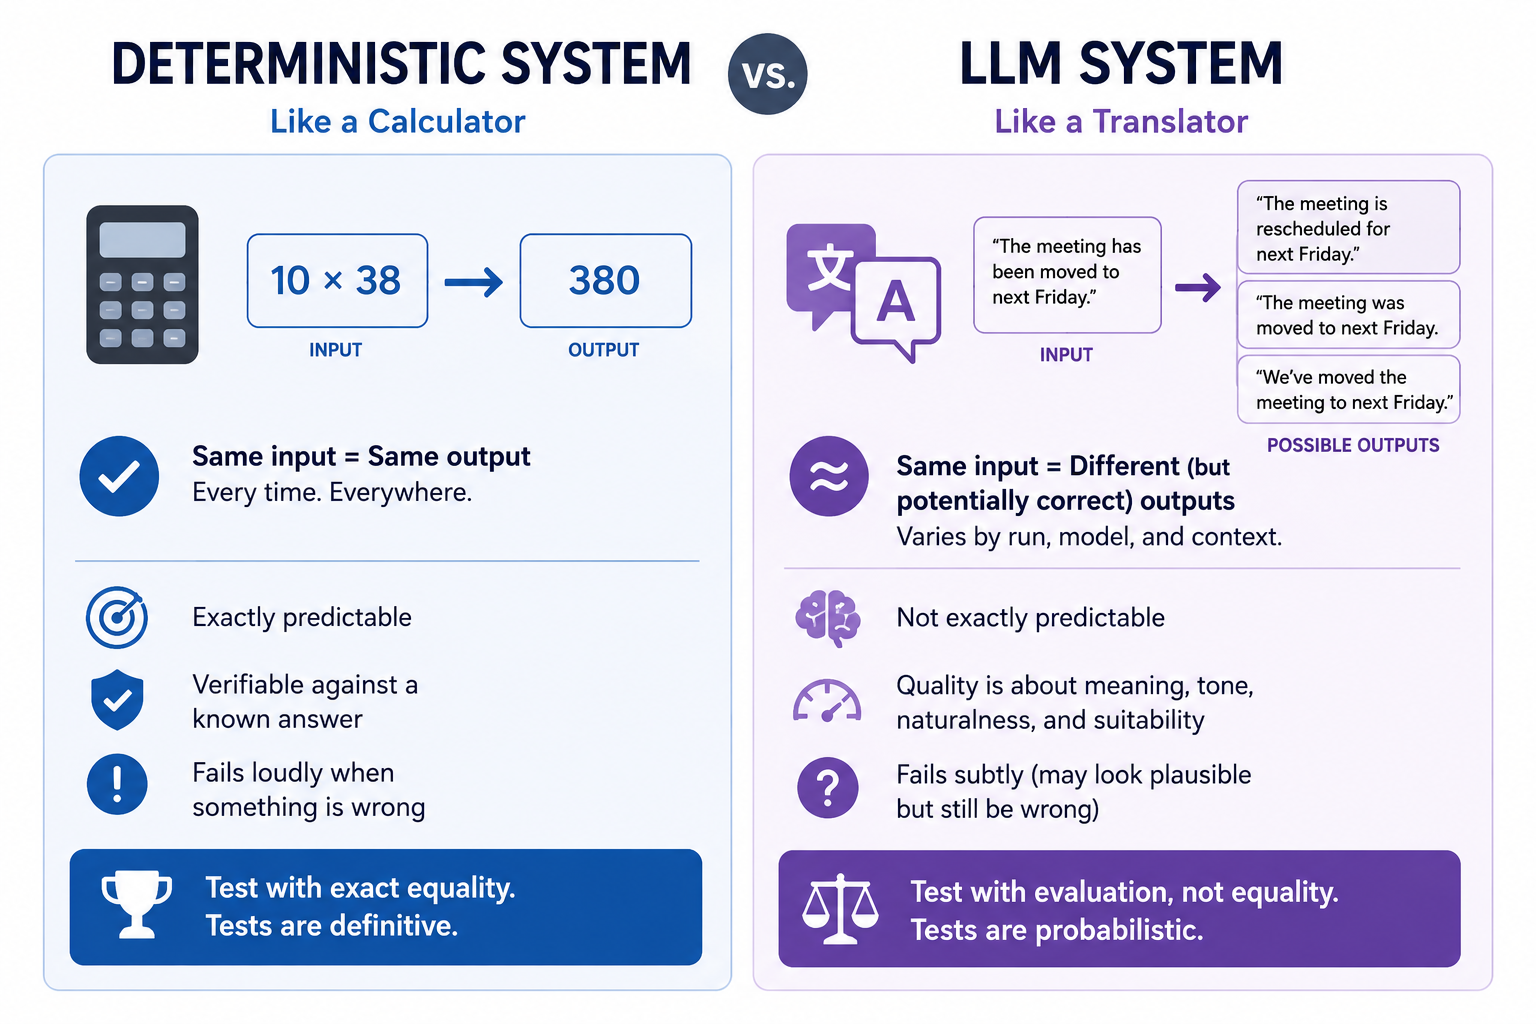
Building and testing an LLM-based system is a different exercise. It is closer to working with a translator than with a calculator. Give a translator the same paragraph twice, and you do not get the same translation. Give the same paragraph to two competent translators, and you get two different versions, both potentially correct, neither matching the other word for word. The quality of a translation is not measured by exact equality to a reference. It is measured against fuzzier criteria: fidelity to meaning, fitness of tone, naturalness in the target language, and suitability for the audience. None of these fit cleanly into the assertion-based testing model that data engineers grew up with.
This is not a small shift. It is a different category of engineering problem, and the practical consequences are not obvious until you have hit them in production. Three things in particular change.
The first problem is that the same input does not produce the same output.
An exact-output assertion suits a deterministic contract; it is one testing technique, not a requirement for all unit tests. Tests can assert properties, bounds, schemas and controlled statistical behavior.
LLM systems break this assumption from the start. Even at temperature zero, where the model is configured to produce its most likely output, two identical prompts can return different responses. The provider may have updated the model behind the endpoint. Your request may have been batched differently. The tokenizer may have been patched. Your test fails. Nothing in your code has changed.
The first instinct is to look for the workaround. Pin the model version. Set a seed. Lock down every parameter you can find. These reduce the variance. They do not remove it because the underlying system is probabilistic, and the provider does not give you the kind of guarantees that traditional software depends on.
What you do instead is harder to describe in a sentence. You stop testing for exact outputs and start testing for the properties of the outputs. Does the response contain the required fields? Is the answer within an acceptable tolerance of correct? Does it avoid the specific failure modes you care about? This is the same shift in property-based testing that was demanded twenty years ago, except now you have no choice.
The second problem is that you cannot enumerate the inputs.
Data pipeline tests cover the cases the engineer thought of. Edge cases, malformed records, schema drift, and null handling. The engineer enumerates these, writes tests, and assumes the universe of inputs is bounded by what was enumerated.
Natural language is not bounded that way. A user can ask anything, in any language, with any framing, with any tone, in any state of confusion or precision. Whatever cases you wrote tests for are an infinitesimally small slice of the inputs your system will see in its first month of production. The cases that cause problems are, by definition, the ones you did not anticipate, because if you had anticipated them, you would have handled them.
This makes test coverage as a metric almost useless. Eighty-seven percent line coverage on your prompt module tells you nothing about how the system behaves on the inputs that actually arrive. You need a different kind of confidence, built from a different practice: curated evaluation sets, adversarial probing, red-teaming, and sustained monitoring of real production traffic. None of this is part of the data engineering toolkit as taught five years ago.
The third problem is the worst one, and it took me the longest to understand.
Data pipelines can fail loudly or silently. Missing columns commonly raise errors rather than automatically producing NULL, while incorrect joins or business rules may yield plausible but wrong data. Reconciliation and semantic checks matter for deterministic pipelines too.
LLMs fail the way a bad translation fails. The output reads confidently. The grammar is correct. The structure is plausible. The format passes every check you can write. But somewhere in the meaning, something is off. A fact is wrong. A nuance is lost. A register has shifted. The model has politely declined to answer something it should have answered, or has confidently invented something that does not exist. There is no exception. There is no schema violation. The system is broken, the user is misled, and you have no signal that anything went wrong unless someone tells you.
I have watched several teams discover this the hard way. The pattern is consistent. The team builds a system, the tests pass, the deploy goes smoothly, and the dashboards stay green for two weeks. Then the support tickets start. The model has confidently invented product specifications, politely refused legitimate questions, or quietly switched between formal and informal registers in the middle of a session. None of this shows up in logs. The team’s instinct, calibrated by years of working with deterministic systems, is to trust the absence of errors. That instinct is wrong here. The absence of errors is the default state of a system producing fluent nonsense.
Correctness has to be verified separately from error states. That means evaluation pipelines comparing outputs against ground truth on a maintained eval set, human review of sampled production traffic, and observability designed to surface semantic drift rather than only latency and throughput. None of this is impossible. It is not even particularly difficult once you accept the problem’s shape. The difficulty is in accepting it.
A hypothetical regulatory-reporting scenario: the story below illustrates a risk, not a verified incident or a universal rule for every bank.
Reporting requirements and sanctions depend on the applicable law and facts. An XSD checks structure and declared constraints, not all business truth. An incorrect record does not automatically imply the same fine under every regime; use the actual reporting rules and control requirements.
Deterministic transformations support repeatable tests and reconciliation, but inputs and encoded rules can still be wrong. Neither passing tests nor a successful submission proves full regulatory correctness.
Now imagine that a senior bank official has attended a conference. The conference said that AI would transform regulatory reporting. The senior person comes back convinced that the existing reporting pipeline is a relic, that an LLM-based agent could replace large parts of it, and that the bank should pilot this approach for the next quarterly submission. The pitch is appealing. The agent will review customer records, determine which positions are reportable, generate the required fields, and produce the output file. Less code, more flexibility, fewer engineers required to maintain it. A modern bank for a modern era. The senior person is not stupid, and the agent does, in fact, produce plausible output during the pilot. The output even matches the previous quarter’s file on most records. Most. The pilot is declared a success. The next quarter, the agent runs in production.
What goes wrong is not what the senior person expected to go wrong. The agent does not fail loudly. It does not crash. It does not produce malformed XML. It produces a file that passes XSD validation, passes internal reconciliation checks for total record counts and aggregate balances, and is submitted to the regulator on time. The file looks correct. The file is not correct. In a small number of cases, the agent has classified a position as non-reportable even though the legislation clearly states it is reportable. The classification was made by an LLM reasoning over the customer’s record, and the LLM produced a confident, well-formatted, plausible answer that was wrong. In other cases, the agent has extracted a customer’s tax residency from a notes field that mentioned the customer’s previous country of residence in passing and used that previous country instead of the current one. In a few cases, the agent has decided that a transaction was below the reporting threshold because the threshold was applied in the wrong currency. None of these failures showed up in the pilot, because the pilot was small enough that the cases did not arise. None of them showed up in the validation because it checks the structure, not the truth. The first signal that anything is wrong arrives six months later, when the regulator’s analysts run their own cross-check against another data source and identify a population of customers who should have been reported and were not.
The bank now has a problem that cannot be solved by fixing the agent. The submission has been made. The records are on file with the regulator as accurate. The remediation will involve restating multiple quarterly submissions, formally notifying the supervisor, and explaining how a bank that has produced this report for fifteen years suddenly missed a population of reportable customers in a single quarter. The senior person who proposed the agent is no longer at the bank. The agent has been quietly removed, and the previous SQL pipeline has been restored. The cost of the lesson, measured in fines, remediation work, and supervisory scrutiny, runs into the seven figures before the legal time is fully billed. The engineering team that warned about this from the start has the unsatisfying experience of being right in a way that helps nobody.
High-stakes reporting needs validated rules, traceability, reconciliation, review and accountable controls. Neither tests nor LLM evaluations provide an unconditional correctness guarantee. Keep generative assistance within a risk-assessed design and verify consequential decisions.
This is the failure mode the rest of this newsletter is about avoiding. Not by refusing to use LLM systems in regulated work, which would be both impractical and a missed opportunity. By understanding precisely which parts of the work tolerate evaluation-grade certainty and which parts demand evidence from tests and reconciliations, and by designing systems that put each kind of component where it belongs. In future issues, I will write about the patterns that make this separation work in practice, including how to use LLMs around a deterministic core rather than inside it, how to evaluate the LLM components rigorously without pretending the evaluation is a substitute for compliance, and how to make the case internally when a senior person comes back from a conference with the wrong idea.
The deterministic parts of your system still benefit from the testing practices you already know. The pipelines that feed the LLM, the structured outputs the LLM produces for downstream consumers, the parsing, the validation, the routing: write unit tests for all of it, the same way you would write tests for any data pipeline. The LLM itself is a different kind of component, and there are common evaluation types built specifically for it.
The roles that screen for this kind of thinking in 2026 are titled things like Senior AI Engineer, AI Platform Engineer, or just Senior Data Engineer at a company that has decided AI is a first-class concern of the data team. A few years ago, none of these roles existed; now they pay a premium over traditional data engineering work, and the supply of credible candidates is thin. The reason for the thinness is exactly what this newsletter exists to address: most senior data engineers have not yet made the move from testing to evaluation, and those who have are mostly people who happened to be in the right place at the right time. The technical content over the next nine Tuesdays is designed to close that gap deliberately, for readers who want to acquire the discipline rather than wait for it to fall into their lap.
Next week, I will write about those evaluation types, what an eval set is, why building one well matters more than almost anything else you do in an LLM project, and how to construct one if you are starting from nothing.
Written by Roland Wenzlofsky, founder of DWHPro and author of Teradata Query Performance Tuning. DWHPro has helped data warehouse practitioners for 15+ years.
Deciding what to change in your data platform?
Compare optimisation, modernisation and migration against your workload and business requirements.