Why I Built My Own Teradata Real-Time MERGE Processor for Apache NiFi Widely read
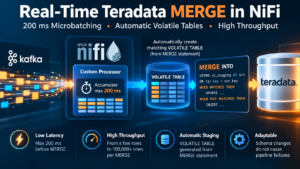
Why I built a Teradata real-time ingestion process for Apache NiFi using 200 ms time-bounded microbatches, automatic VOLATILE TABLE generation and set-based MERGE.
Why I built a Teradata real-time ingestion process for Apache NiFi using 200 ms time-bounded microbatches, automatic VOLATILE TABLE generation and set-based MERGE.
Why data warehouse professionals have been doing “bronze, silver, gold” for over 20 years. If you have been working in data warehousing for any length of time, the first time you heard about the “medallion architecture” you probably had one reaction: We already do this. You were right. The medallion architecture, popularized by Databricks as …
Database features should be compared based on their documented behavior, their operational impact, and the architectural principles behind them. This applies especially to physical optimization structures such as Teradata Join Indexes (JIs) and Snowflake Materialized Views (MVs)—two features often mentioned together during migration planning, yet substantially different in scope and design. The intention of this …
Learn how to easily load a CSV file into a Teradata database using Python with minimal code. No need for complex scripts or ETL tools. Read more.
Functions on Join Columns and Their Impact on Teradata Performance In many Teradata systems, developers apply functions directly in join conditions to work around data-model inconsistencies.While this approach might seem harmless, it can dramatically affect optimizer decisions and query performance — and often reveals deeper data-model issues. 🎓 Prefer video? Lecture 12 of my Udemy …
Have you encountered a poorly designed physical data model where object columns are distributed randomly across tables, and you wish to unify them in their rightful place? Merging non-historical tables is simple, but the process becomes more complex when historization is applied to at least one of the tables. The fragments below illustrate interval overlap; …
Learn about the goals of SQL tuning and how to optimize database performance by reducing resource usage. Skew, IOs, and CPU seconds are key metrics. Discover how to ensure completeness and correctness of Teradata statistics, detect missing and stale statistics, and improve query plans.
1. Statistics In Teradata, understanding and managing statistics is essential for optimizing database performance. Statistics provide the optimizer with precise data about stored information, allowing for well-informed decisions when handling queries. This article will explore the significance of statistics in Teradata, their effect on query performance, and recommended methods for upkeep. The Role of Statistics …
The DBQL example needs configured logging and a bounded time window. HASHAMP()+1 assumes the relevant map/AMP scope; it may misrepresent a request using only a subset of AMPs. Use the actual participating-AMP count for meaningful skew/impact calculations, and clear temporary query bands after the measured workload. 1. Complete and up-to-date Statistics At the start of …
Learn about Teradata Volatile Tables, their features, restrictions, and performance tuning possibilities. Find answers to common questions about their usage.
We count visits without cookies and without storing anything on your device. With your permission, we also use Google Analytics for our Google Ads integration and remember which campaign brought you here. We do not record sessions. You can decline and still use the site. Privacy details.
Protected by Security by CleanTalk and CleanTalk Anti-Spam