Teradata Join Strategies Explained in 6 Minutes (Video) Widely read
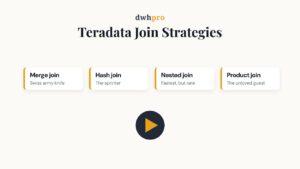
A six-minute video on how Teradata joins work: why matching rows must share an AMP, redistribution vs. duplication, and the merge, hash, nested and product join.

A six-minute video on how Teradata joins work: why matching rows must share an AMP, redistribution vs. duplication, and the merge, hash, nested and product join.
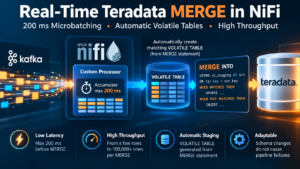
Why I built a Teradata real-time ingestion process for Apache NiFi using 200 ms time-bounded microbatches, automatic VOLATILE TABLE generation and set-based MERGE.
Load isolation sounds like a feature that should improve concurrency. After all, it’s one of the primary reasons for enabling it: data should be loaded while applications and users continue to query the table without being unnecessarily disturbed by the load. Watch: why load isolation can block your readers This video walks through the deadlock …
Learning path: Internals and operations. View the suggested reading order. This reference includes release-specific examples; check the version context before applying a technique. This guide collects the material on this site about how Teradata behaves underneath the SQL — what the database does when it is under pressure, how it protects and isolates data, and …
Learning path: Compression and space. View the suggested reading order. This reference includes release-specific examples; check the version context before applying a technique. Teradata gives you more than one way to store the same data in less space, and they behave very differently once queries start reading it back. This guide brings together the compression …
Learning path: Physical design. View the suggested reading order. This reference includes release-specific examples; check the version context before applying a technique. Most Teradata performance problems are designed in long before anyone writes the query. This guide collects the physical design material from this site — the data model, the staging and preparatory layers, partitioning …
Learning path: SQL tuning and rewriting. View the suggested reading order. This reference includes release-specific examples; check the version context before applying a technique. The cheapest Teradata tuning available is almost never a new index. It is rewriting the query so the optimizer has less work to do and better information to do it with. …
Start with the tested SQL: The practical Teradata statistics guide includes COLLECT STATISTICS syntax, before-and-after EXPLAIN estimates, sampling and recollection examples tested on Teradata 20.00.28.81. The specialist examples below retain their original release context and were not retested in that lab. 🎓 Prefer video? Lecture 14 of my Udemy course Teradata Performance Tuning in Practice, …
Database features should be compared based on their documented behavior, their operational impact, and the architectural principles behind them. This applies especially to physical optimization structures such as Teradata Join Indexes (JIs) and Snowflake Materialized Views (MVs)—two features often mentioned together during migration planning, yet substantially different in scope and design. The intention of this …
Performance degradation caused by uneven workload distribution is one of the oldest and most persistent challenges in parallel data warehouse systems. Both Teradata and Snowflake can experience this imbalance, commonly known as skew. Although the term is shared, the mechanics differ fundamentally: Teradata can suffer from both persistent and runtime skew, whereas Snowflake’s skew occurs …
We count visits without cookies and without storing anything on your device. With your permission, we also use Google Analytics for our Google Ads integration and remember which campaign brought you here. We do not record sessions. You can decline and still use the site. Privacy details.
Protected by Security by CleanTalk and CleanTalk Anti-Spam