Loading a text file into a Teradata database can be arduous without the use of intricate scripts. However, generating TPT scripts or depending on ETL tools like Informatica, AB Initio, and Datastage can be a protracted process. A more straightforward alternative is to utilize Teradata in conjunction with Python. This article will show how to load a CSV file into a Teradata database with minimal code. It is important to mention that this approach is most suitable for smaller files as fastload or multiload protocols will not be utilized.
Preparing the CSV test file
We generate a testing table consisting of three columns with INTEGER data types, then proceed to import the subsequent CSV file.
1,2,3
4,5,6
7,8,9
10,11,12
The Python Script
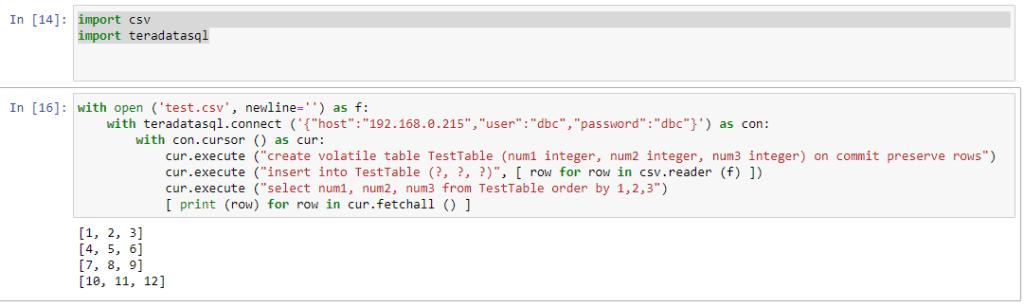
We begin by importing the CSV file into a temporary Teradata table, which is immediately reread. The data is retrieved as a list, where each row contains several easily accessible columns within the list element.

Get the complete Teradata tuning book, free
Teradata Query Performance Tuning: The DWHPro Guide
By Roland Wenzlofsky & Artemios Vogiatzis
206 pages on statistics and demographics, access paths and indexes, query execution plans, and joins. Get the full PDF and practical Teradata updates from DWHPro.
Confirm your email to receive your download link. Privacy policy. Unsubscribe in any newsletter.
About the free bookThis small-file example reads the complete CSV into memory. It maps blank numeric fields to NULL, validates numeric text, optionally skips a declared header and avoids submitting an empty batch. Supply credentials privately through the process environment. The database fixture validated parsing and inserts, including quoted numbers; it did not validate Jupyter or Windows installation.
import csv
import teradatasql
import csv
import os
import teradatasql

has_header = False  # Set True only when this input has a header.
with open('test.csv', newline='', encoding='utf-8') as f:
    reader = csv.reader(f)
    if has_header:
        next(reader, None)
    rows = []
    for fields in reader:
        if len(fields) != 3:
            raise ValueError('Expected three CSV fields')
        rows.append([None if value.strip() == '' else int(value) for value in fields])

with teradatasql.connect(host=os.environ['TD_HOST'],
                         user=os.environ['TD_USER'],
                         password=os.environ['TD_PASSWORD']) as con:
    with con.cursor() as cur:
        cur.execute('CREATE VOLATILE TABLE TestTable (num1 INTEGER, num2 INTEGER, num3 INTEGER) ON COMMIT PRESERVE ROWS')
        if rows:
            cur.execute('INSERT INTO TestTable (?, ?, ?)', rows)
        cur.execute('SELECT num1, num2, num3 FROM TestTable ORDER BY 1,2,3')
        for row in cur.fetchall():
            print(row)
Building or improving a data pipeline?
Discuss ingestion, transformations, orchestration, quality checks and operational handover.
Get the complete Teradata tuning book, free
Teradata Query Performance Tuning: The DWHPro Guide
By Roland Wenzlofsky & Artemios Vogiatzis
206 pages on statistics and demographics, access paths and indexes, query execution plans, and joins. Get the full PDF and practical Teradata updates from DWHPro.
Confirm your email to receive your download link. Privacy policy. Unsubscribe in any newsletter.
About the free book
Thanks for the share
A large number of examples for this library can be found on github
https://github.com/Teradata/python-driver/blob/master/samples/BatchInsPerf.py