“The illiterate of the 21st century will not be those who cannot read and write, but those who cannot learn, unlearn, and relearn.”
Alvin Toffler
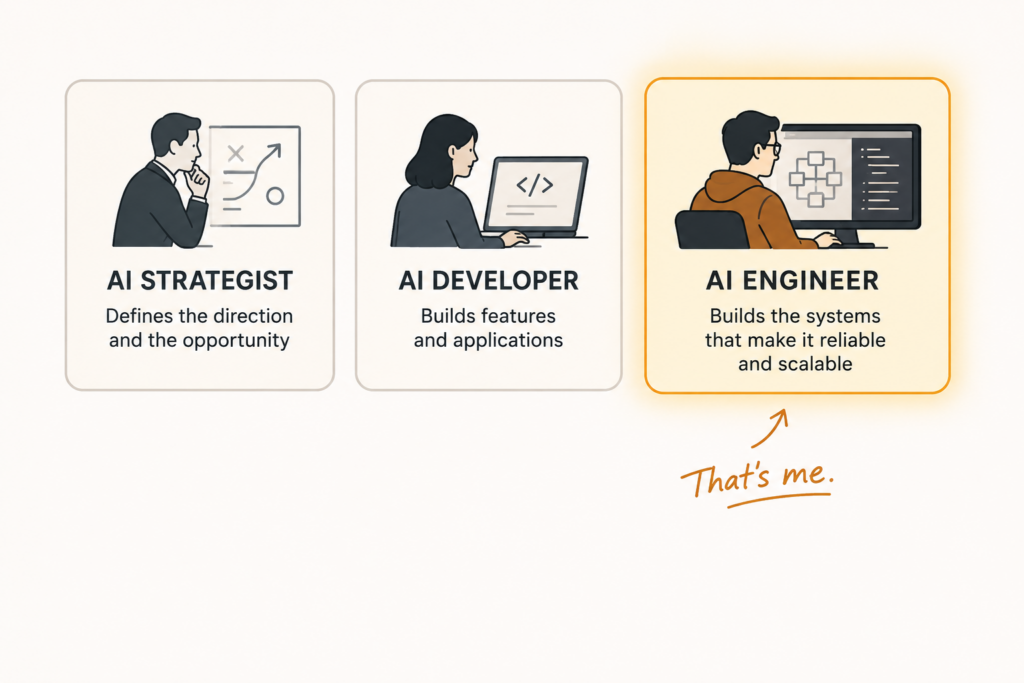
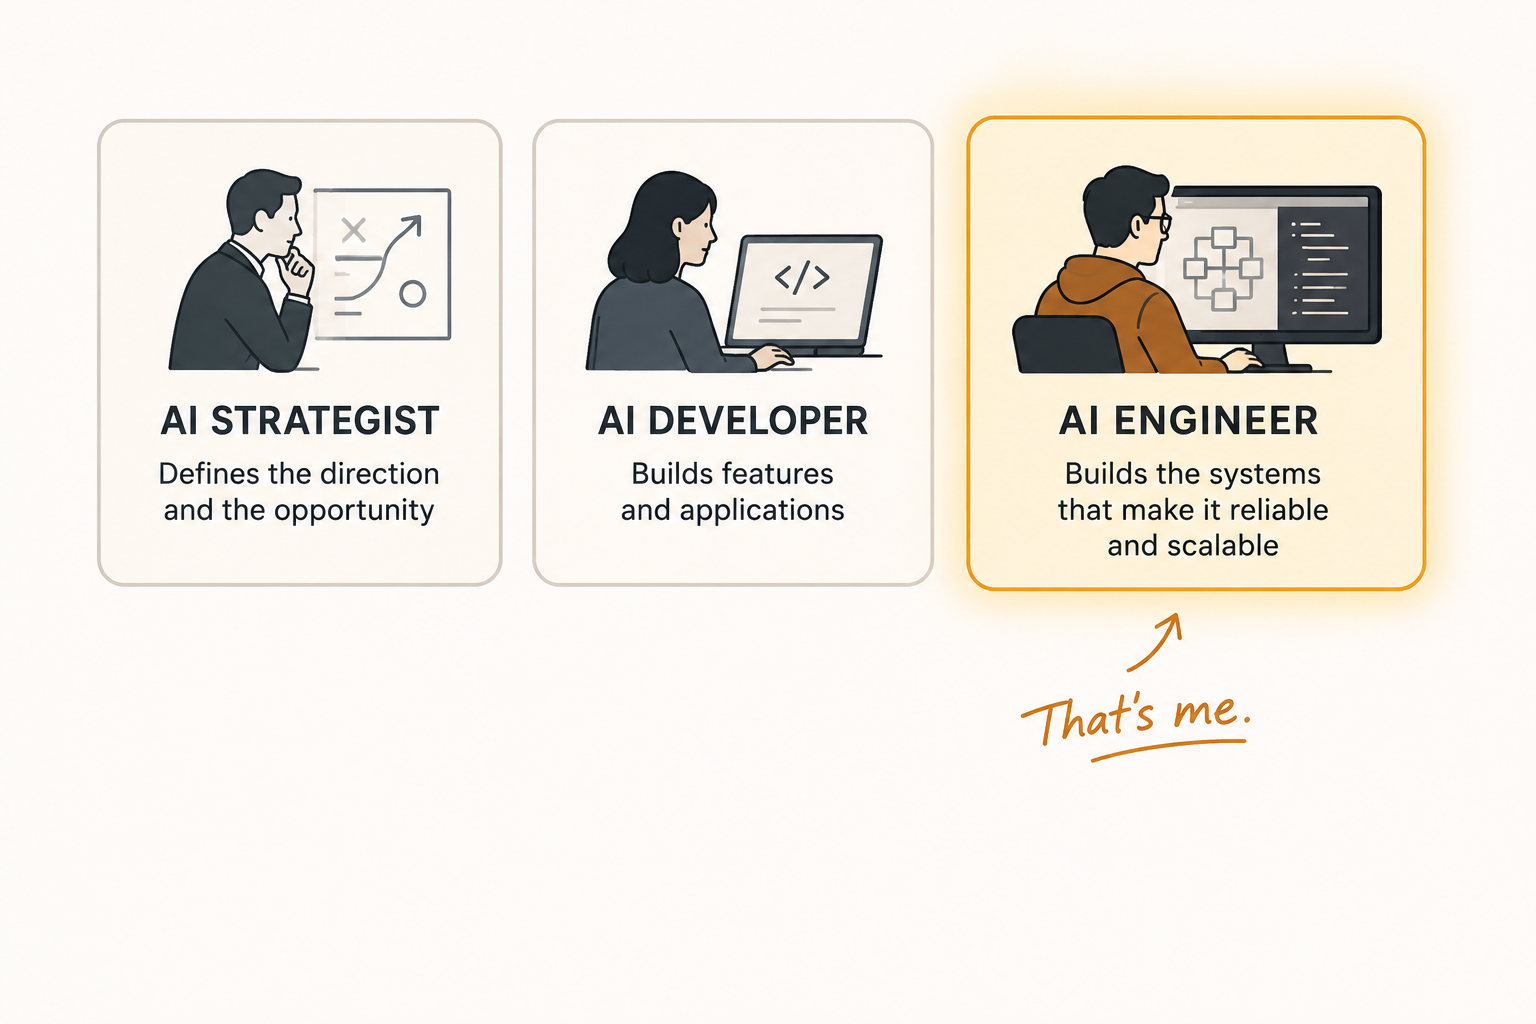
Open any job board, scroll any LinkedIn feed, sit through any earnings call, and you will run into the same wave of new titles: AI engineer, AI developer, AI strategist, machine learning engineer. The titles are everywhere. The functions behind them are often unclear, sometimes interchangeable, and the role descriptions on the postings rarely match the work being done.
There are sincere versions of all of these roles, doing real work, filled by people who have earned the title. I respect them.
But this is not, in my experience, why most of these positions are being created right now.
Companies are hyped about AI, and the hype is not entirely innocent. It came right on the heels of something else: the great pandemic over-hiring. Between 2020 and 2022, employers, tech ones in particular, hired as if growth would never bend. Headcounts doubled. Layers were added on top of layers. Then the curve bent.
The advantage of an AI revolution is that it gives executives a story to tell. We are not correcting an over-hire; we are transforming. We are not cutting heads; we are reallocating to AI. We are not admitting we misread the demand curve; we are responding to a once-in-a-generation technology shift. The story is cleaner than the truth, and it sounds visionary on a quarterly call.
Reports about enterprise AI pilots raise useful questions about adoption and measured business value, but the cited NANDA study’s sample and methodology do not establish that 95% of all AI projects fail. Treat its scope separately from a forecast for every company and assess your own evaluation and financial evidence. Related reading: Yahoo Finance
Consider a fictional composite: a company replaces customer-service capacity with a poorly governed chatbot, discovers fabricated answers, and has to rebuild human support. This illustrates integration and oversight risks; it is not a sourced account of one identifiable company.
If this newsletter does only one thing, let it be this: do not become one of these people.
I bring this up not to be cynical, but to be useful. If your role has been touched in this round, whether eliminated, narrowed, or reorganized into the AI org, it helps to see the situation for what it is. In many cases, you were not replaced by a model. You were caught in a correction that had been brewing for two or three years, and AI is the label now being placed on it.
If you have been sitting with some version of did I fail to keep up, the question is honest, and from what I have heard this year, almost universal. It is also the wrong question. The right one is what do I do with what I already know.
That distinction matters because it changes what to do next.
I write this from inside the field. More than twenty-five years of building enterprise data warehouses, watching the same architectures get renamed every five years, and clients ask the same questions in a new language. I was caught on the wrong side of one of these corrections myself once, in a different decade and under a different acronym. The path is real because I have walked some version of it.
I am writing this for people in a hard moment, possibly the hardest of their professional lives. The point is not to dress that up. The point is to show, concretely, that what comes next is shorter than it currently looks, because most of what you need for the next step is already in your hands.
If you have spent the last fifteen or twenty years building data systems, the path into AI is more direct than the hype suggests. There is a role that takes most of what you already know and asks for a smaller, defined set of new things. It is not the role being most loudly marketed right now. It is the role being most quietly filled by experienced practitioners while everyone else is fighting over titles.
The AI Engineer
An AI engineer, in the sense I am using it, does not train foundation models. They take the models that already exist (GPT, Claude, Gemini, Llama, and the open alternatives) and integrate them into things people actually use: customer-facing applications, internal tools, document processing, contact centers, decisioning systems, and embedded software in physical products. The work is to build a bridge between a model produced by OpenAI, Anthropic, or Google and a product or process that can benefit from it.
The engineering, in other words, is in the integration. The model itself is somebody else’s problem. Your problem is making it useful, reliable, fast enough, cheap enough, and integrated cleanly into a system that already exists.
That is a different job from training. It is also a very familiar shape for anyone who has spent years building data pipelines.
Alongside the integration work, the AI engineer is responsible for model adaptation: making a generic foundation model fit a specific use case. This is done through three main techniques:
- Prompt engineering: getting useful behavior out of the model by being precise about what you ask it for.
- Retrieval-augmented generation, usually shortened to RAG: wiring the model up to your own data so its answers are grounded in your reality, not the open internet.
- Fine-tuning: adjusting the model itself on examples of the behavior you want, when prompting and RAG are not enough.
All three are practical engineering disciplines. None of them requires you to invent a new neural architecture or read a research paper to start.
The current AI engineer’s toolbox, in enterprise terms, looks roughly like this:
- Python, fluently. It is the language of the field, and it carries the data and AI libraries you will use (pandas, NumPy, among them).
- Access to foundation models through enterprise platforms: Azure OpenAI Service, AWS Bedrock, Google Vertex AI, or Anthropic’s enterprise tier. Most production AI workflows go through one of these, behind your existing identity, audit, and procurement controls.
- Orchestration frameworks that wrap foundation model calls, handle retries, manage context, and let you swap one model for another without rewriting the application. The open-source landscape here is volatile and rarely passes an enterprise architecture review on its own. Most enterprises end up with either a vendor framework (Azure AI Foundry, the Bedrock SDK, Vertex’s orchestration layer) or a thin in-house wrapper they own and control.
- Vector storage and search, which holds embeddings, the numerical representations of text that make RAG work. Increasingly built into platforms you already use: Azure AI Search, OpenSearch with vector indices, Databricks Vector Search, Snowflake Cortex, or Postgres with the right extensions.
- Cloud services and containers (Docker, Kubernetes, if you are unlucky).
- A solid working understanding of large language models (LLMs) and how natural language processing actually works under them.
The next section spells out, in detail, what you already bring to this list, and what you need to add. I call this the Four-Fifths Rule. Two visible lists make it concrete.
What You Already Bring, and What You Need to Add
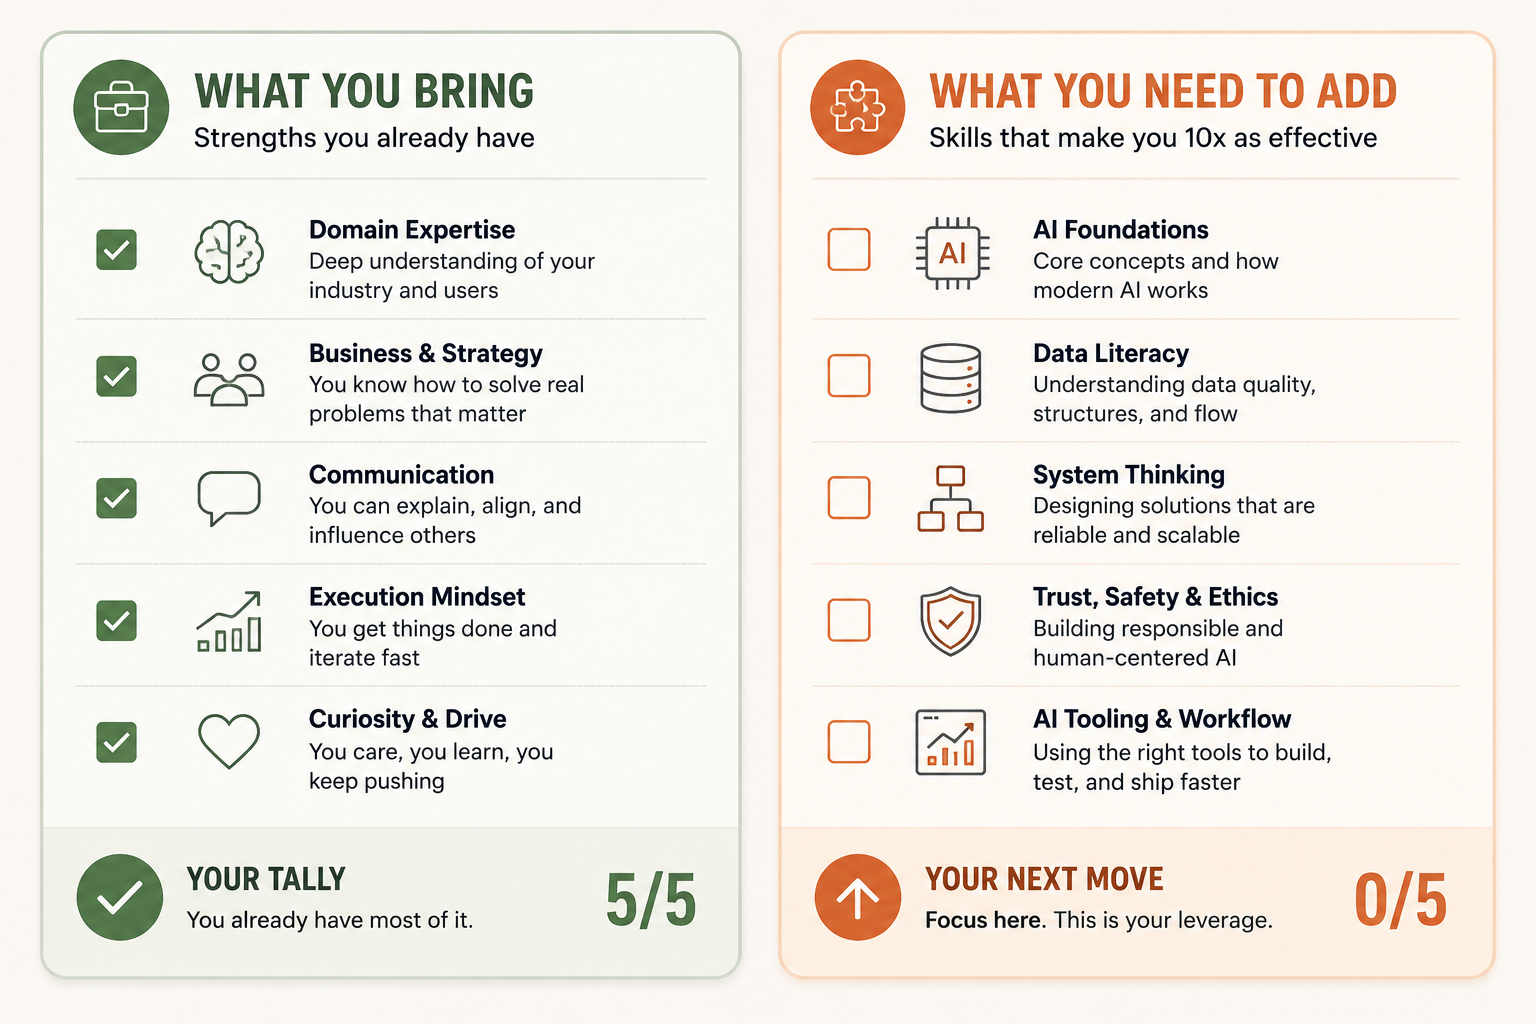
Look at the AI engineer role honestly, and the picture for an experienced data engineer or developer becomes clear: most of the work is already in your hands, and the rest is a bounded gap you can close in months rather than years.
Here is what already transfers, directly, without translation:
- Python and the data ecosystem: assess actual proficiency rather than assuming every SQL or ETL engineer already knows Python, cloud services and API deployment.
- SQL and data manipulation. The work of getting data into shape so a model can use it is the work you have been doing your entire career.
- Pipelines, ETL, ELT. RAG and most AI applications are pipeline patterns. You have built variants of them for years.
- Data quality, lineage, governance. A model is only as good as the data behind it. You already know this in your bones.
- Cloud platforms and containers. AWS, GCP, Azure, Docker, Kubernetes, if you must. The deployment side of AI applications looks almost identical to deploying any other production service.
- API design. Calling a foundation model is the same as calling an API. Wrapping a model in a service is the same as designing an API. Familiar territory.
- Production discipline. Monitoring, observability, latency, cost control, fallback paths, and graceful degradation. This is the part most pure-AI people are weakest at, and it is exactly the part you spend your life thinking about.
- Working with stakeholders. You have spent years translating between business requests and technical reality. This skill is in unusually short supply on newly assembled AI teams.
Now the honest part. Here is what you do not automatically bring, and what you will need to add:
- Large language model fundamentals. How transformers work, what attention is, what tokenization does to your text, and what a context window costs you in practice. Not deep enough to publish papers, deep enough to make good engineering choices.
- Prompt engineering as a discipline. It looks easy from the outside, and it is not. Treating prompts as code, versioning them, evaluating them systematically: real skills, learned by doing.
- Embeddings, vector search, and RAG. The data shape is new, even if the surrounding infrastructure is familiar. Building a useful RAG pipeline involves making real decisions you have not made before.
- Fine-tuning workflows. When to fine-tune, when to use a smaller model, when to just prompt better. Practical know-how, mostly absorbed through projects.
- Working with non-deterministic systems. This is the biggest mental shift. The same input does not always produce the same output. Your testing strategy, your observability, your idea of what a bug looks like, all of it has to adjust.
- AI evaluation methodology: unit tests still apply to deterministic pipeline components, schemas and output constraints. Add representative evaluation sets and human review for variable generated content.
Three to six months is a planning heuristic for some experienced engineers, not a measured transition time or employment guarantee. Audit your starting skills, build real projects and evaluate the gaps before setting a timetable.
That is the timeline if you can dedicate yourself fully. For many of you, that will not be possible. The realistic version looks like nights, weekends, a course or two, a side project that turns into a portfolio piece, and possibly a contract role somewhere in the middle that pays the bills while you learn. The skills compound either way. The timeline stretches, but the destination does not move.
And on that contract point, experienced data engineers and developers are a known and well-paid commodity in this market. AI engineering contracts exist; they pay competitively, and the people hiring for them know that someone who has run production data systems for 15 years is worth more than someone who has spent 6 months learning prompt engineering on YouTube. You are not asking for charity; you are repricing the work you already know how to do.
To make this concrete. A senior data engineer I have worked with on and off for the better part of a decade was let go last year, after fifteen years at a European banking client. She spent about four months closing the LLM gap on nights and weekends, took a contract role helping a competitor of her old employer integrate an Azure OpenAI pilot into their fraud-detection workflow, and is now leading the AI engineering practice at that competitor. The path looks shorter from the outside than it felt from the inside. The destination was where I told her it would be.
This is not, by any honest measure, starting from scratch.
The AI Developer
There is a smaller, harder role on the other side of all this. If you have ever wondered who builds the foundation models themselves, that is the AI developer. They are the engineers at OpenAI, Anthropic, Google, Meta, and a growing list of governments, open-source groups, and well-funded labs, producing GPT, Claude, Gemini, Llama, and their open competitors.
Building a foundation model is one of the most expensive and technically punishing exercises in modern computing. To compete in this space requires sustained R&D, deep familiarity with the field of deep learning research, and a willingness to live at the edge of a field that changes every month. The skill list reads like a small university degree:
- Python at a fluent level, plus the data ecosystem
- Statistics, linear algebra, calculus, and probability, deep enough to read research papers
- Working knowledge of deep learning architectures and transformer internals
- NLP foundations: tokenization, vector embeddings, semantic similarity
- Production engineering: Docker, containerization, DevOps
- Useful though not mandatory: API design and cloud platform experience
This is one of the most demanding roles in tech today. If you already have a deep background in ML research, the path is open. For most readers, it is the role to be aware of, not the one to aim at. And to be clear: this is the bar for building foundation models. The AI engineer role we covered above, the one most of you will actually do, does not require this depth.
The AI Strategist
A final note on the title you keep seeing everywhere.
An AI strategist is the most hyped and least understood of the AI titles. In its sincere form, it is a real, technical role. Someone with a deep AI background and senior business experience helps a company decide what to actually do with the technology, how to deploy it, how to measure it, and how to get it adopted internally. The profile (technical depth, comprehensive business understanding, senior-level soft skills) is rare, and companies pay accordingly when they can find it. Most of the time, they cannot, and they hire consultants. That works for closing a capacity gap, but consultants should never become the exclusive holders of the strategy. When the engagement ends, they walk out with the knowledge, and the customer is left running a program nobody on staff fully understands.
For most readers of this newsletter, the strategist label is not the role to aim at this year. It may, however, be the C-suite version of the same career you start at the AI engineer level today.
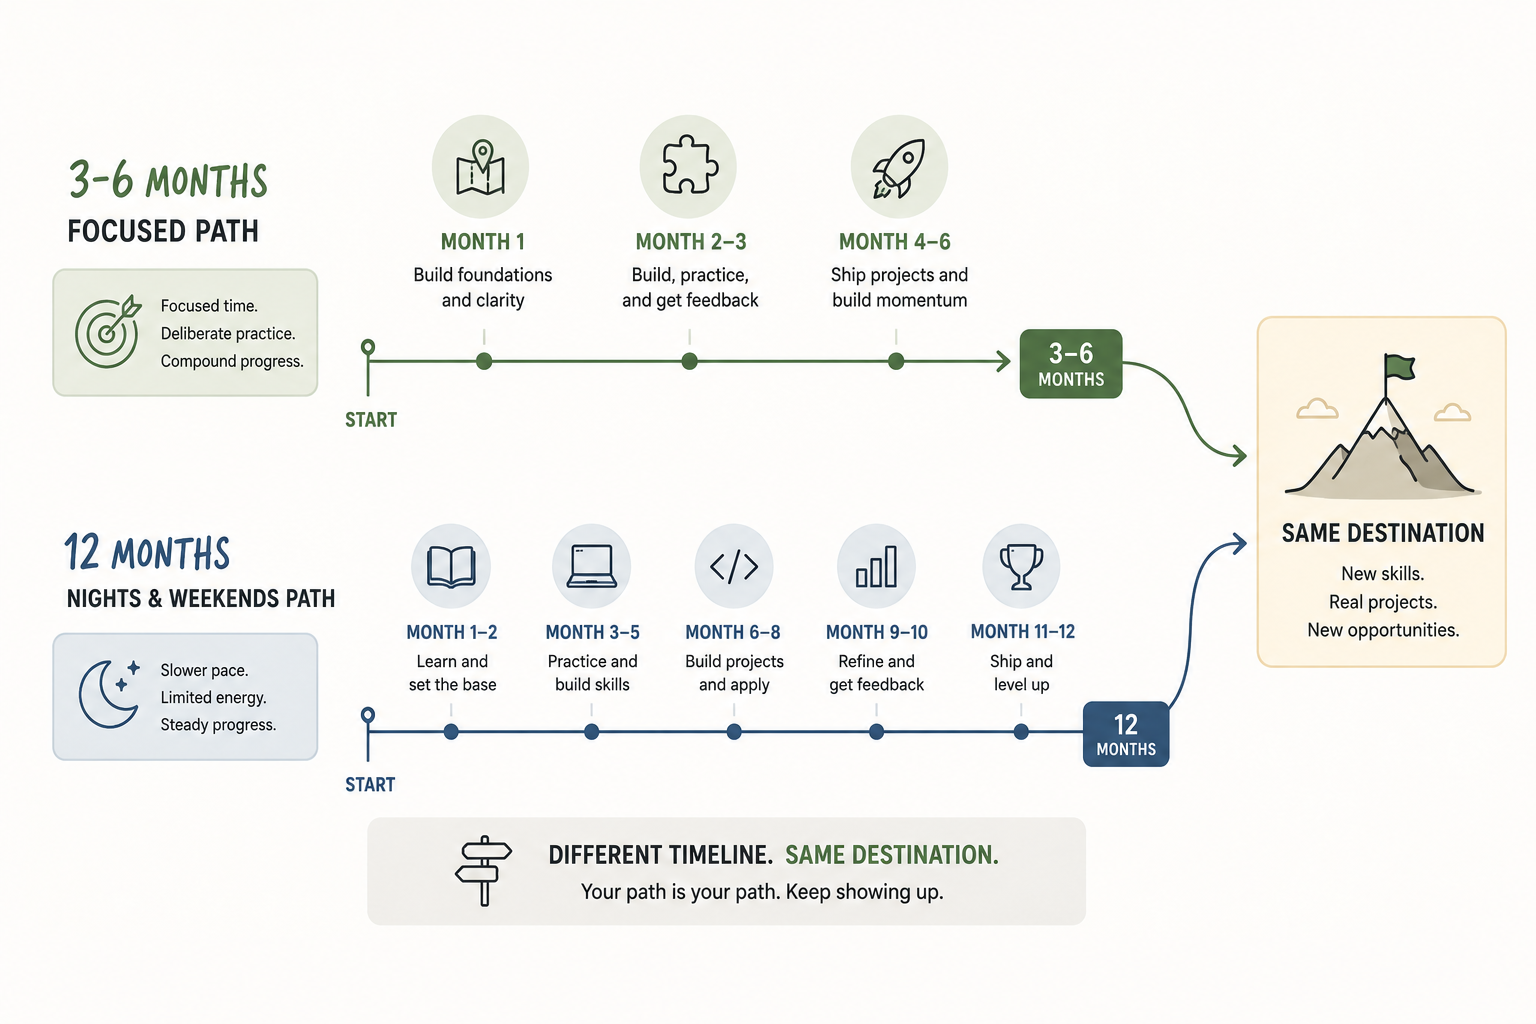
The Four-Fifths Rule is my heuristic for emphasizing transferable skills, not measured 80% job coverage. The AI engineer/developer labels in this article are an author-defined taxonomy; employers use them differently.
Here is the practical first step. Tonight, after the day’s noise has died down, open one of the enterprise foundation model consoles (Azure OpenAI Service, AWS Bedrock, Anthropic’s API, or Google Vertex AI), sign up, and make your first call. Ask the model to explain how a transformer works, or how to design a basic RAG pipeline. Twenty minutes from now, you will have done your first piece of AI engineering. The first step looks small because it is.
If you want one resource to anchor the weeks that follow, two options that both work for a single weekend. Andrej Karpathy’s Intro to Large Language Models on YouTube (free, around an hour) builds the right mental model from first principles. Or the Anthropic prompt engineering guide in their official documentation, also free, makes you measurably better at the discipline within a few hours. Either is a good place to start.
And you are not making this transition alone. Thousands of experienced data engineers and developers are walking the same path this year. The route is well-trodden enough now that you can see the footprints. Follow them, and write back to me when you get to the other side.
Until next week, build something tonight.
Written by Roland Wenzlofsky, founder of DWHPro and author of Teradata Query Performance Tuning. DWHPro has helped data warehouse practitioners for 15+ years.
Deciding what to change in your data platform?
Compare optimisation, modernisation and migration against your workload and business requirements.