Teradata’s Secondary Index offers an alternative means of accessing rows, minimizing disk I/Os during data retrieval.
Part of the Teradata Physical Design and Data Modelling guide.
Despite their widespread use in database systems, Teradata employs an alternative to B+ Tree Indexes.
Teradata categorizes secondary indexes into unique (USI) and non-unique (NUSI). Despite their similar names, they differ in functionality. The following article pertains solely to USI.
USI rows are hashed by the secondary-index values. Their physical subtable is not a standalone table object, but index definitions are visible through DBC.IndicesV. Uniqueness does not guarantee perfectly even AMP distribution.
The primary index column(s) hash the base table data, whereas the secondary index rows are hashed by different columns or combinations of columns, providing an additional path for data.
The USI row includes the ROWID of the corresponding base table row, enabling a direct lookup of said row.

Get the complete Teradata tuning book, free
Teradata Query Performance Tuning: The DWHPro Guide
By Roland Wenzlofsky & Artemios Vogiatzis
206 pages on statistics and demographics, access paths and indexes, query execution plans, and joins. Get the full PDF and practical Teradata updates from DWHPro.
Confirm your email to receive your download link. Privacy policy. Unsubscribe in any newsletter.
About the free bookAccess to Teradata USI is typically limited to 2 AMPs. Initially, a lookup is performed on the secondary index row, which includes the ROWID for the base table. This ROWID is then used to locate the base table row. Occasionally, the USI row and the base table row are situated on the same AMP, resulting in AMP-local retrieval of the base table row.
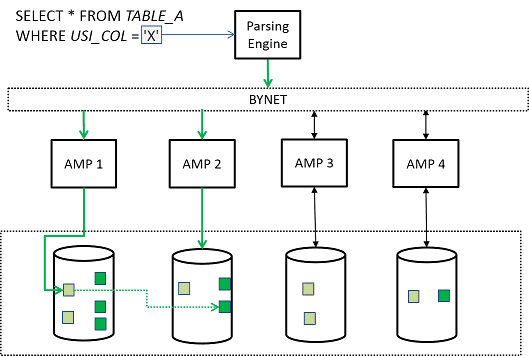
A USI provides an alternate unique access path; hash collisions and finite populations mean uniqueness alone does not eliminate all distribution skew.
Do not apply a NUSI-style 10% selectivity rule to a unique-equality lookup. The audited USI lookup worked without collected statistics. Statistics can still inform broader query costing.
Evaluate index use across the workload, storage and maintenance costs. Before dropping a USI, determine whether it enforces a business constraint; one EXPLAIN that does not use it is not sufficient reason to remove it.
Information about the Teradata USI you will find nowhere else:
The meticulous process of retrieving data.
- The Parsing Engine consults the hash map and locates the AMP carrying the USI row.
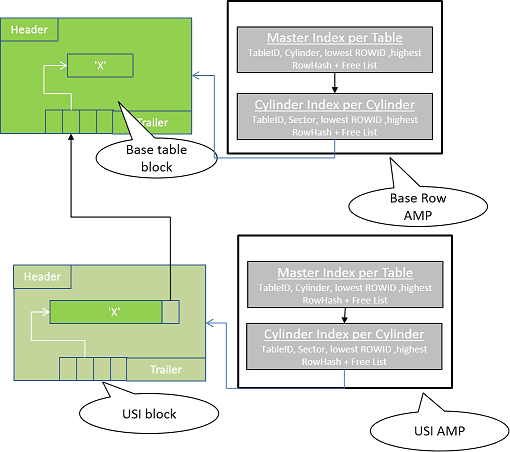
- The AMP containing the USI row finds the USI data block via the Master Index & the Cylinder Index.
- The USI data block is moved into the FSG cache.
- The AMP does an in-memory binary search of the data block and locates the USI row.
- The designated row carries the ROWID of the base table. The Parsing Engine uses this ROWID to look up the base table AMP and instructs it to retrieve the base table row.
- The base table AMP locates the data block via Master Index & Cylinder Index lookup.
- The base table AMP moves the data block into the FSG cache.
- The base table row is located with an in-memory binary search on the base table block.
See also:
The Secondary Index in Teradata – The NUSI compendium
The Teradata Join Index Guide – We leave no questions unanswered!
The Teradata Partitioned Primary Index (PPI) Guide
Watch the Teradata Indexing Video Course
Need help with query performance or platform costs?
Diagnose plans, skew, spool pressure and expensive workloads. Agree a baseline and acceptance criteria before making changes.
Get the complete Teradata tuning book, free
Teradata Query Performance Tuning: The DWHPro Guide
By Roland Wenzlofsky & Artemios Vogiatzis
206 pages on statistics and demographics, access paths and indexes, query execution plans, and joins. Get the full PDF and practical Teradata updates from DWHPro.
Confirm your email to receive your download link. Privacy policy. Unsubscribe in any newsletter.
About the free book
Hi Mayank,
While the PI is the way Teradata distributes the records across all AMPs, the USI is working exactly the same way. Hence, you can imagine the USI as being the same table or some columns of the same table being hashed by a different PI. If the USI is covering all columns a query needs, Teradata has not even to lookup the related base table record, otherwise, the ROWID of the base table record which is stored in the USI record will be used to find the related base table row.
Hi Roland,
Thank You for all the articles on your blog. Kudos to you!
“Exactly the same as a unique primary index, the unique secondary index distributes evenly across the AMPs and there is no need to take care of data skewing.”: I think that only the Primary Index is responsible for distributing the table records across AMPs. Please correct me if I am mistaken.
Thanks,
Mayank