The History of Parallel Database Architectures
Parallel computing has existed for over three decades, and parallel database architectures followed shortly thereafter.
Part of the Teradata Internals and Operations guide.
It all began with the shared memory architecture, which remains widely used in servers today.
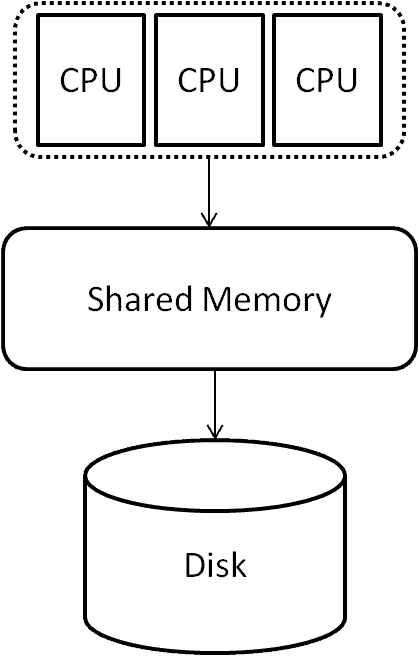
The shared memory architecture is a multiprocessor system with shared memory, a single operating system, and a shared disk or storage area network designated for data storage. The processes are distributed across the CPUs.
Shared-memory scalability is constrained by hardware and contention, but there is no universal processor ceiling applicable to all systems.
Current databases use two architectures: shared disk and shared-nothing (Teradata is based on the latter).
Both designs resolve the issue of limited scalability.
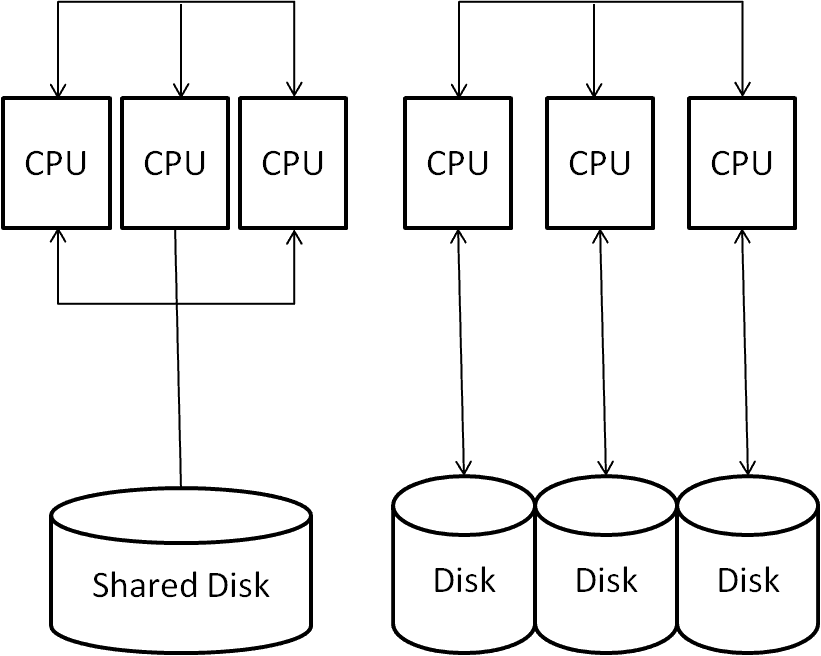
Shared disk architecture involves network-based communication among processors, storing data solely on a shared disk or a storage area network. This type of architecture comprises two distinct networks – one for inter-processor communication and another for communication with the disk storage system.
The shared-nothing design employs individual local disks for every processor, with processor communication exclusively reliant on the network.
Databases employing this architecture execute parallel queries, with data distributed across disks in a shared-nothing configuration.
Teradata experts can quickly identify the association between the shared-nothing configuration and the AMPs, storage units, and processor communication network known as BYNET.
A crucial objective of a database system with a shared-nothing architecture is to ensure equitable data distribution among the available disks. Teradata accomplishes this by hashing the primary index columns and storing the rows on the corresponding AMPs.
Column storage groups data by columns or column sets; it need not place each column on a different node or disk. Physical distribution is a separate design choice.
Parallel databases and fault tolerance
Parallel databases are currently cutting-edge technology. However, fault tolerance remains a significant challenge for parallel databases, regardless of the underlying architecture.
Architectures perform well with a limited number of processors, as the likelihood of processor failure is minimal in such scenarios.
The probability of a failure depends on component reliability, time interval and dependence between failures. A large processor count alone does not make failure mathematically certain.
Shared-nothing systems can be fault-tolerant. In Teradata, fallback/storage protection and node restart or virtual-processor migration serve different roles. A hot standby node provides recovery capacity; it is not simply a dedicated network data-replication node.
When comparing parallel databases to the Map-Reduce Framework (see related article for details), the parallel file system (HDFS) and fault handling stand out as a strong foundation for ensuring fault tolerance.
Suitability for batch processing depends on the workload, execution engine and configuration; MapReduce is not universally better than a parallel database.
The following Hadoop and SQL-H observations describe a historical period, not current integration availability.
Historically, vendors explored combining SQL interfaces and Hadoop processing. Assess present options using current support and feature documentation.
SQL-H is a historical example in this discussion; its mention is not a recommendation for a current deployment.
Deciding what to change in your data platform?
Compare optimisation, modernisation and migration against your workload and business requirements.