The Teradata Primary Index and Hash Collisions
Primary-index data types, character sets and collations can materially affect hashing, comparison and join conversions. Choose types for correct business semantics and compatible joins; benchmark relevant access paths before changing them.
Part of the Teradata Physical Design and Data Modelling guide.
This article addresses a performance issue with CHARACTER columns in the primary index. Although not as apparent as skew, this problem is often overlooked and remains hidden.
Assuming a Teradata system with 160 AMPs and 20-bit hash buckets, we create a table with a primary index of a CHARACTER(8) column that contains 100 million phone numbers. The 20-bit hash buckets allow for 1,048,576 unique hash buckets. The hashing algorithm is expected to provide:
- Each hash bucket is used approx. 95 times
- Each AMP receives approx. 625,000 rows
- Hash collisions remain possible and expected at this scale; a 32-bit hash does not uniquely encode 100 million arbitrary inputs
We computed the DSW, AMP, and collision count for every possible input value.
The historical chart describes bucket occupancy for this particular input. Uniform random hashing has variance, not a perfect impulse distribution. A peak of 43,000 buckets is about 4.1% of 1,048,576, not 25%. The original 100-million-row workload was not reproduced.
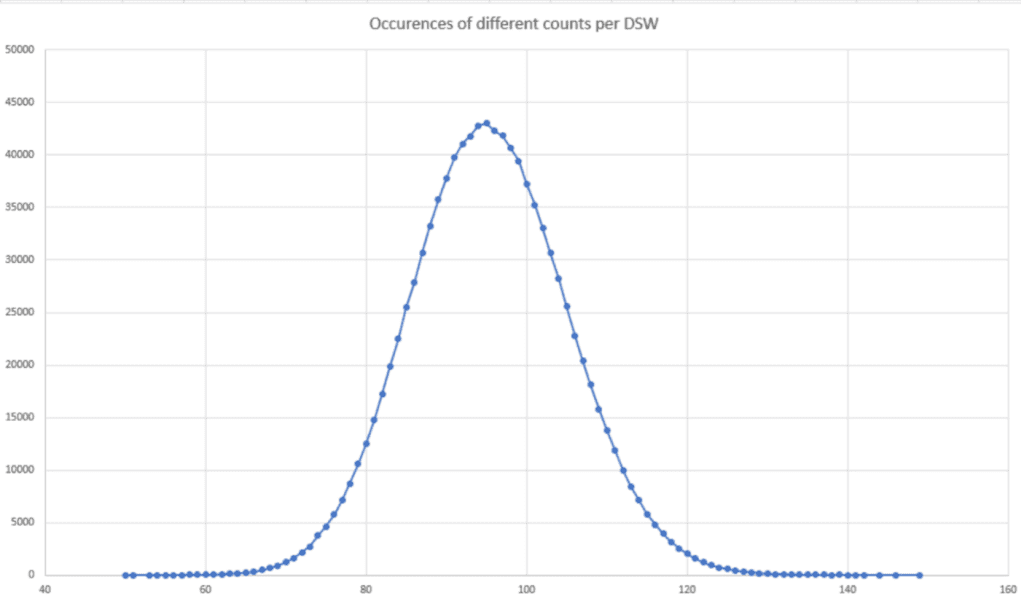
Upon closer examination, it becomes evident that the equitable allocation of rows across the AMPs is not the underlying issue. Each AMP receives an almost identical number of rows, ranging from 623,000 to 627,000. Rather, the problem lies in generating hash collisions on all AMPs, as demonstrated in the subsequent graph.
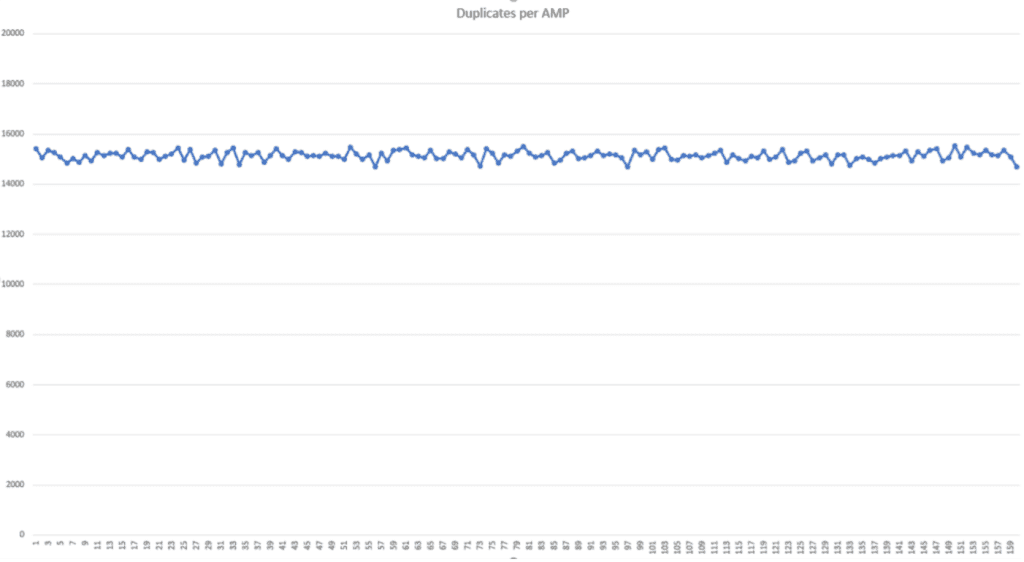
The algorithm produced around 15,000 hash collisions per 160 AMPS. Most of these collisions result from three or four primary index values being linked to the same hash value. This is concerning, as hash collisions have a negative impact on performance.
Let’s revisit the scenario, but this time, we store the phone numbers in a BIGINT column and employ it as the Teradata Primary Index. We create a table containing 100 million rows. The resulting graph corresponds to our expectations for the CHARACTER column.
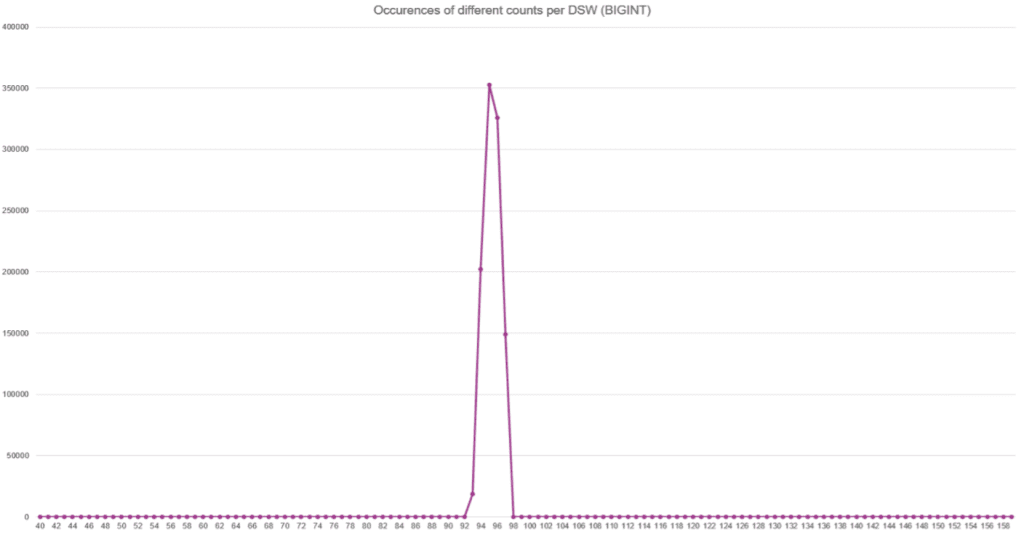
The historical numeric sequence reportedly produced bucket counts of 93–98 and no duplicate hashes in that sample. This does not imply collision-free BIGINT hashing. A separate audit fixture of 200,000 distinct random BIGINT values produced 199,993 distinct row hashes. It disproves the universal claim but is not a production collision-rate benchmark.
Summary
Using CHARACTER columns in the primary index may result in numerous hash collisions. While the contents of such columns are usually limited, this may not be a concern. Nevertheless, significant performance issues may arise in exceptional scenarios where millions of distinct values are present in the primary index column.
Do not change a primary-index data type solely from these historical charts. Numeric conversion can lose leading zeros or alter comparisons, and incompatible types can change join plans. Measure skew, collisions and query cost for the actual domain before a redesign.
This article will illustrate additional factors to consider when selecting the Primary Index for optimal performance.
Need help with query performance or platform costs?
Diagnose plans, skew, spool pressure and expensive workloads. Agree a baseline and acceptance criteria before making changes.