Teradata Partitioning – Row vs. Column
Partitioning tables using column or row partitioning can reduce resource usage when accessing data.
Part of the Teradata Physical Design and Data Modelling guide.
Row partitioning horizontally partitions tables, allowing the optimizer to limit data access to a cluster of rows. On the other hand, column partitioning vertically partitions tables, enabling the optimizer to restrict data access to a subset of columns.
The rows of partitioned tables are stored in physical clusters, which are groups of rows. For instance, a cluster may contain all the rows from a specific date.
Partition elimination requires a usable predicate for the partition expression. Merely mentioning a date or partitioning column does not guarantee that only one partition will be read; confirm the chosen access path with EXPLAIN.
Partitioned tables and non-partitioned tables are stored similarly, with rows distributed across all AMPs and organized by partition number, row hash value, and uniqueness value. In fact, non-partitioned tables are stored internally like partitioned tables, with all rows belonging to the dummy partition 0.

Get the complete Teradata tuning book, free
Teradata Query Performance Tuning: The DWHPro Guide
By Roland Wenzlofsky & Artemios Vogiatzis
206 pages on statistics and demographics, access paths and indexes, query execution plans, and joins. Get the full PDF and practical Teradata updates from DWHPro.
Confirm your email to receive your download link. Privacy policy. Unsubscribe in any newsletter.
About the free bookRow-partitioned tables store each row in a single physical row on a disk.
Column partitioning clusters one or more table columns to create partitions. Each partition represents a cluster. Physical rows within column-partitioned tables contain a subset of columns and do not represent complete logical rows.
Row partition clustering allows for complex expressions to be utilized, whereas column partitioning is restricted to the columns’ definition and creates a single cluster. Therefore, column partitioning is more straightforward to implement.
Row-partitioned tables offer the advantage of partition elimination, which allows the optimizer to limit search activity to the accessed partition when a query selects only one partition. This eliminates the need for a full table scan.
Column partitioned tables offer the advantage of selecting a subset of columns, thereby decreasing disk IO.
Combining column and row partitioning in a single table can enhance resource utilization.
The following unpartitioned DDL supplies a conceptual column layout. The illustrations compare four hypothetical layouts; this CREATE statement does not define or test row, column or combined partitioning. A runnable comparison needs separate valid definitions and identical data on a system supporting those features.
CREATE SET TABLE THE_TABLE (COL_A INTEGER, COL_B INTEGER, COL_C INTEGER, COL_D INTEGER, COL_E INTEGER, COL_F INTEGER);We are executing this query:
SELECT SUM(COL_A) FROM THE_TABLE WHERE COL_C IN (2,3,4);The illustrations assume row partitioning on COL_C and separate column containers for COL_A and COL_C. These are explanatory assumptions, not features implemented by the unpartitioned DDL above.
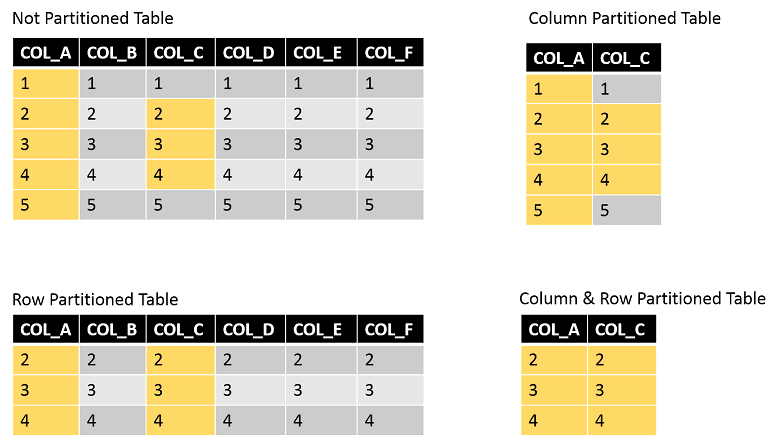
- In the case of a column-partitioned table, all five rows but only two columns have to be accessed.
- All five rows and columns must be accessed in the non-partitioned table.
- All columns, but only three rows, must be accessed in a row-partitioned table.
- Only three rows and two columns must be accessed in a row and column-partitioned table.
Choosing the right partitioning can optimize resource utilization. However, it is crucial to understand your workload, as each partitioning approach has distinct pros and cons based on the type of workload. To learn more, please refer to our article on the Teradata columnar feature.
Need help with query performance or platform costs?
Diagnose plans, skew, spool pressure and expensive workloads. Agree a baseline and acceptance criteria before making changes.
Get the complete Teradata tuning book, free
Teradata Query Performance Tuning: The DWHPro Guide
By Roland Wenzlofsky & Artemios Vogiatzis
206 pages on statistics and demographics, access paths and indexes, query execution plans, and joins. Get the full PDF and practical Teradata updates from DWHPro.
Confirm your email to receive your download link. Privacy policy. Unsubscribe in any newsletter.
About the free book