Teradata Query Parallelism
Teradata can execute scans, joins, sorts and aggregations in parallel. The chosen plan determines how many AMPs participate; a primary-index lookup can use one AMP, and dependencies may serialize parts of a request.
Part of the Teradata Internals and Operations guide.
Teradata’s uniqueness lies in its ability to apply parallelism at every step of the query process. This advantage resulted from its architectural design, which integrated high levels of parallelism from the start, even when most components were hardware-based. As a result, Teradata has a significant advantage over other database systems.
The architecture of Teradata has enabled the implementation of additional features to enhance parallelism over time. Without it, many advancements would not have been achievable.
Parallel Execution across the AMPs
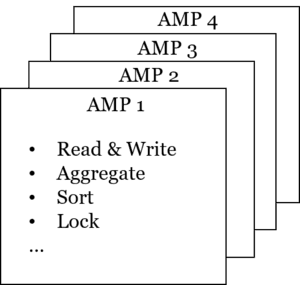
AMPs execute assigned data-processing work. A request may involve one AMP, a subset or many AMPs; the execution plan and dependencies determine participation and when results can be returned.
The AMP level’s parallelism is a primary factor contributing to the exceptional performance of a properly utilized Teradata System.
AMPs are versatile and able to perform any task without specialization.
Numerous AMPs are presently accessible on every Teradata System.
The Tasks of a Teradata AMP
- Reading of Rows
- Writing of Rows
- Row Locking
- Sorting
- Aggregating
- Index creation and maintenance
- Maintaining the transaction log
- Backup and Recovery
- Bulk and Transactional Loading
The Components of a Teradata AMP
An AMP manages logical execution and storage resources; their physical allocation depends on the platform.

Get the complete Teradata tuning book, free
Teradata Query Performance Tuning: The DWHPro Guide
By Roland Wenzlofsky & Artemios Vogiatzis
206 pages on statistics and demographics, access paths and indexes, query execution plans, and joins. Get the full PDF and practical Teradata updates from DWHPro.
Confirm your email to receive your download link. Privacy policy. Unsubscribe in any newsletter.
About the free book- Logical storage unit
- Memory
- CPU
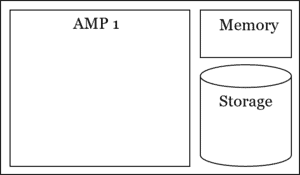
In the classic architecture, AMPs manage their portions of the data and execution resources. Physical CPU, memory and storage arrangements depend on deployment. Adding hardware does not guarantee linear performance growth.
The Teradata Primary Index – Hash Partitioning
Hashing and maps distribute primary-index rows. Repeated values, hash collisions, maps and query redistribution can produce skew, so hashing alone does not ensure equal work.
Hash partitioning efficiently distributes large data sets to AMPs, but imbalanced task distribution can create bottlenecks on individual AMPs, resulting in skewing and increased pressure.
Addressing skew is a primary concern for a performance tuner working on a Teradata system.
To implement hash partitioning, designate one or more columns in each table to calculate a hash value, determining the corresponding AMP for a given row. These columns are referred to as the Primary Index.
CREATE TABLE Customer(Customer_ID BIGINT NOT NULL,Lastname VARCHAR(500),Firstname VARCHAR(500)) UNIQUE PRIMARY INDEX (Customer_Id);Teradata Pipelining Steps
Pipelining further enhances query parallelism by allowing steps to begin before their predecessors are complete.
A request consists of multiple subtasks, as previously mentioned. These subtasks can include, for instance:
- Read all rows of a table (simple step)
- Update a subset of table rows (simple step)
- Read two tables, redistribute them, and join them (complex step)
Steps can have different complexity, and AMPs may also need to interact with each other.
Through pipelining, the join process can commence while the involved tables’ rows are still being redistributed, despite its complexity.
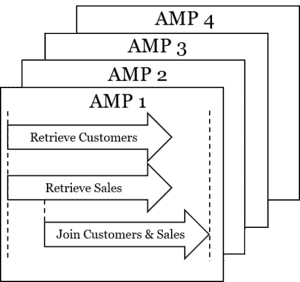
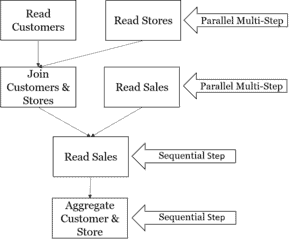
Teradata Parallel Multi-Steps
Pipelining involves nested steps where the predecessor’s input is readily accessible to the successor. Additionally, Teradata offers an extra layer of parallelism.
Independent steps can be executed simultaneously.
The Teradata BYNET
Teradata operates on a shared-nothing architecture where work is executed in parallel by the AMPs.
To facilitate communication among AMPs, the BYNET network serves as the medium for exchanging messages and data.
The Tasks of the BYNET
BYNET is not just an ordinary network; it possesses unique features tailored specifically for Teradata.
- Message Delivery: Guarantees that messages arrive at the target AMP
- Coordinate multiple AMPs working on the same step
- Sorting of the final result set when sending to the client
- Minimizes the number of AMPs needed for a step
- Congestion control to avoid an overloaded network
Message Passing & the BYNET
To comprehend the functions of BYNET, it is imperative to introduce a novel virtual process known as the Parsing Engine, which is accountable for generating the execution plan of a request. BYNET serves as the intermediary between the Parsing Engine and the AMPs.
Messages can be sent from the Parsing Engine via BYNET to the AMPs, but BYNET is also responsible for the AMP-to-AMP communication.
BYNET can transmit messages to all or a selected group of AMPs.
Sorting the Final Answer Set
What sets Teradata apart from others?
When the query requires ordering, sorting and merge work may be parallelized across components. Only an explicit outer ORDER BY guarantees the order of the result delivered to the client.
- Each AMP locally sorts its data (this is done in parallel)
- Each Node takes one buffer of data from all its AMPs and sorts it (buffer by buffer by AMP)
- The BYNET passes one buffer per Node to the Parsing Engine, which does the final sort.
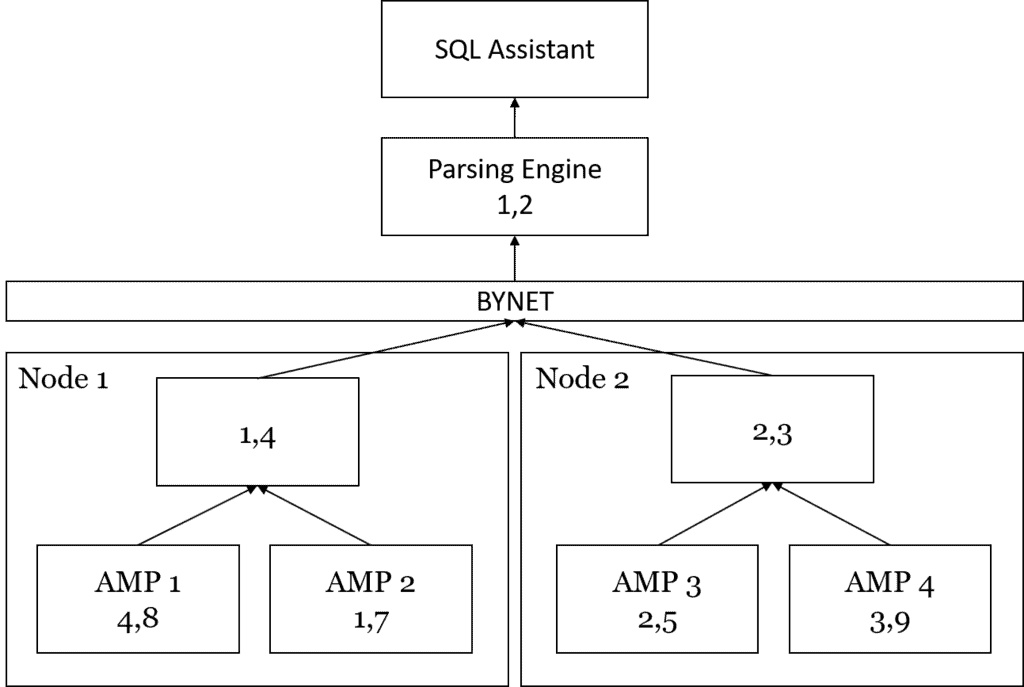
The Teradata Shared Nothing architecture comprises these vital elements. Further information regarding data storage is available here:
Deciding what to change in your data platform?
Compare optimisation, modernisation and migration against your workload and business requirements.
Get the complete Teradata tuning book, free
Teradata Query Performance Tuning: The DWHPro Guide
By Roland Wenzlofsky & Artemios Vogiatzis
206 pages on statistics and demographics, access paths and indexes, query execution plans, and joins. Get the full PDF and practical Teradata updates from DWHPro.
Confirm your email to receive your download link. Privacy policy. Unsubscribe in any newsletter.
About the free book