Teradata error 2646, “No more spool space,” means a request could not obtain the spool space it needed. Check the failing query, per-AMP skew, concurrent sessions, and the effective user or profile limit before increasing the allocation. Free space in a system-wide total does not rule out a limit on one AMP.
Part of the Teradata Internals and Operations guide.
Watch: why one AMP runs out of spool
This video walks through the lab test in this article step by step: the same 10,000 rows, two primary indexes, and why only one of them hits error 2646.
Reproducing error 2646: the same 10,000 rows, a different primary index
Tested 24 October 2026 on Teradata 20.00.28.81, BTEQ 20.00.00.11, BTET mode, four AMPs. In an isolated lab account with a 16,000,000-byte spool limit (4,000,000 bytes per AMP), three inserts into a volatile table indexed on a constant key failed with error 2646. Three inserts of the same rows into a table indexed on the distributed id succeeded. We did not increase the limit.
The synthetic source contained 10,000 rows: ids 0–9,999, a hot_key of 1 on every row and a CHAR(200) payload. Source and target were MULTISET volatile tables. The source used PRIMARY INDEX(id); the two targets differed only in their primary index. Each target was emptied before its next attempt.
-- Failing target definition:
CREATE MULTISET VOLATILE TABLE dwhpro_bench_skew
AS dwhpro_bench_source WITH NO DATA
PRIMARY INDEX(hot_key) ON COMMIT PRESERVE ROWS;

-- Corrected target definition:
CREATE MULTISET VOLATILE TABLE dwhpro_bench_even
AS dwhpro_bench_source WITH NO DATA
PRIMARY INDEX(id) ON COMMIT PRESERVE ROWS;

-- Same source rows in each request:
INSERT INTO dwhpro_bench_skew SELECT * FROM dwhpro_bench_source;
INSERT INTO dwhpro_bench_even SELECT * FROM dwhpro_bench_source;| Target PI | Attempts | Result | BTEQ elapsed times |
|---|---|---|---|
| Constant hot_key | 3 | Error 2646 each time; no target rows retained | 1, 1, 1 seconds before failure |
| Distributed id | 3 | 10,000 rows inserted each time | 1, 1, 1 seconds to completion |
What changed in EXPLAIN?
The failing plan redistributed by the hash of hot_key and sorted a spool estimated at 10,000 rows / 2,210,000 bytes. Since the key was constant, those rows went to one AMP. The corrected plan merged directly from the source into the target on the same map, without that redistribution/sort step. Changing the PI changed both distribution and the plan; this experiment does not isolate their individual contributions.
What did the spool counters show?
After the first successful insert, CurrentSpool was 1,294,336, 2,342,912, 2,351,104 and 2,351,104 bytes on Vprocs 0–3. These are account snapshots including retained volatile data and measurement overhead, not the request’s peak spool. Post-failure counters cannot reconstruct the peak because failed-request spool has already been released. The EXPLAIN byte count is an estimate, not a measured peak.
This is a bounded failure-and-fix demonstration, not a production sizing rule or a speedup claim. BTEQ reported whole seconds; the timings cannot support a percentage improvement. Other releases, AMP counts, space policies and workloads may behave differently. Choose a primary index for the complete workload, including join access and distribution.
Download the SQL, complete sanitized results and reproduction instructions. Use a dedicated lab account: the script deliberately causes three spool errors. It creates only its own volatile tables. The disposable account used for this test was removed afterward.
How to investigate error 2646
| Check | Evidence to collect | Next action |
|---|---|---|
| Query expansion | EXPLAIN estimates, join conditions and actual step metrics where available | Correct unintended row multiplication and review relevant statistics. |
| Skew | Per-AMP usage during the failing request | Identify skewed joins or data distribution; a total alone is insufficient. |
| Shared consumption | Concurrent requests and retained volatile tables for the user | Release unneeded temporary data and review workload concurrency. |
| Limits or capacity | User/profile spool settings and physical-space availability | Ask the DBA to distinguish allocation, profile, skew policy and physical capacity. |
Check current spool usage with a read-only query
Lab verification: 22 October 2026. The example below was executed on Teradata Database 20.00.28.81 using BTEQ 20.00.00.11 in Teradata (BTET) transaction mode. Each SQL statement was submitted as a separate request. These are small functional checks, not performance benchmarks; results involving transaction boundaries can differ in ANSI mode or an explicit transaction.
Get the complete Teradata tuning book, free
Teradata Query Performance Tuning: The DWHPro Guide
By Roland Wenzlofsky & Artemios Vogiatzis
206 pages on statistics and demographics, access paths and indexes, query execution plans, and joins. Get the full PDF and practical Teradata updates from DWHPro.
Confirm your email to receive your download link. Privacy policy. Unsubscribe in any newsletter.
About the free bookSELECT DatabaseName,
SUM(CurrentSpool) AS current_spool_bytes,
SUM(MaxSpool) AS max_spool_bytes
FROM DBC.DiskSpaceV
WHERE DatabaseName = USER
GROUP BY 1;The query completed successfully in the lab. It returned 425,984 current spool bytes and 99,230,829,772 maximum spool bytes for the lab account at that instant. These are environment-specific observations, not recommended allocations or an estimate for your workload. Access to DBC views depends on your privileges.
CurrentSpool is current usage, not the failed query’s peak. MaxSpool is the configured database/user allocation represented in this view, not available physical disk space. A profile spool limit and your system’s space-management settings may also apply. Aggregating across AMPs hides skew; ask your DBA to inspect the per-AMP rows and the failing request in Viewpoint or query logs. A sample taken after a failure may miss the peak because the request has already released its spool.
The 22 October diagnostic subsection tested metadata syntax only. The separate 24 October constrained-account experiment above deliberately induced error 2646; these are different experiments. Related: Teradata DiskSpaceV columns, profile limits and usage notes.
Teradata Spool Space Introduction
What is Teradata Spool Space?
Teradata uses Spool Space as a temporary workspace to store intermediate and final result sets. This space is only used temporarily and is released when it is no longer needed or automatically at the end of the session. Later in this article, we will explain the four categories of Spool Space.
How can we increase the spool space in Teradata?
First distinguish a user spool limit from a lack of available physical space. A DBA can review the user or profile limit, while query tuning and appropriate compression can reduce demand. Removing fallback protection changes resilience, and dropping indexes can harm other workloads; neither is a routine spool-space fix. Review these trade-offs before changing physical design or adding capacity.
What should I do if my system no longer has enough space?
A spool shortage and a permanent-space shortage require different checks. Both reads and data-modification workloads can need spool, and a failed data-modification request may require rollback. Identify the failing request and resource before changing an allocation.
How is Teradata Spool Space assigned to a User?
During the user creation process, maximum spool space allocation can be established.
-- Template only: replace the parent, user name and password before use.
CREATE USER DWHPRO_ADMIN FROM DWHPRO AS
    PERMANENT = 800000000 BYTES,
    SPOOL = 200000000 BYTES,
    PASSWORD = <your_password>;
A user’s spool setting is a limit, not a reservation of physical disk. The allocation is represented per AMP; profile settings and global space-accounting or spool-skew policies can affect the effective limit. Check the configuration for your release.
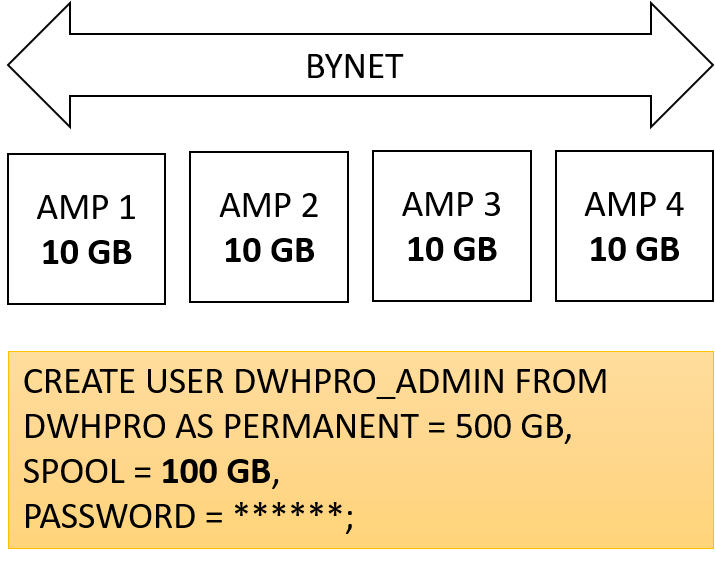
I get the Error Message “No more spool space in user…” although enough space should be available. Why?
Changing AMP topology can change per-AMP allocation and data placement, but does not by itself prove less physical disk per AMP. Distinguish the configured user/profile spool limit from physical capacity and map/distribution changes.
How is Spool Space managed internally by Teradata?
Understanding that Teradata does not concurrently store data and spool space on the same cylinder is crucial. Consequently, Teradata swiftly releases cylinders once they are no longer needed for spool space usage.
How can I find out how much Spool Space my User has?
SELECT *
FROM DBC.DatabasesV
WHERE DatabaseName = 'DWHPRO';
Why is there even a Teradata Spool Space Limit?
Establishing this limit is crucial to abort requests that consume excessive resources. Although high spool space usage does not necessarily imply a poorly constructed query, there is a strong correlation between suboptimal queries and increased spool space consumption.
What “no more spool space” Scenarios are there?
The absence of available cylinders on the Teradata system could be a contributing factor. It is imperative to avert a scenario where all cylinders reach capacity. Typically, the DBA establishes a distinct database on each Teradata system to allocate and reserve space, thus circumventing the depletion of free cylinders.
Excessive parallel sessions from a single user can also deplete available spool space. Skewed queries can also result in “no more spool space.”
What must we consider for NOPI Teradata tables?
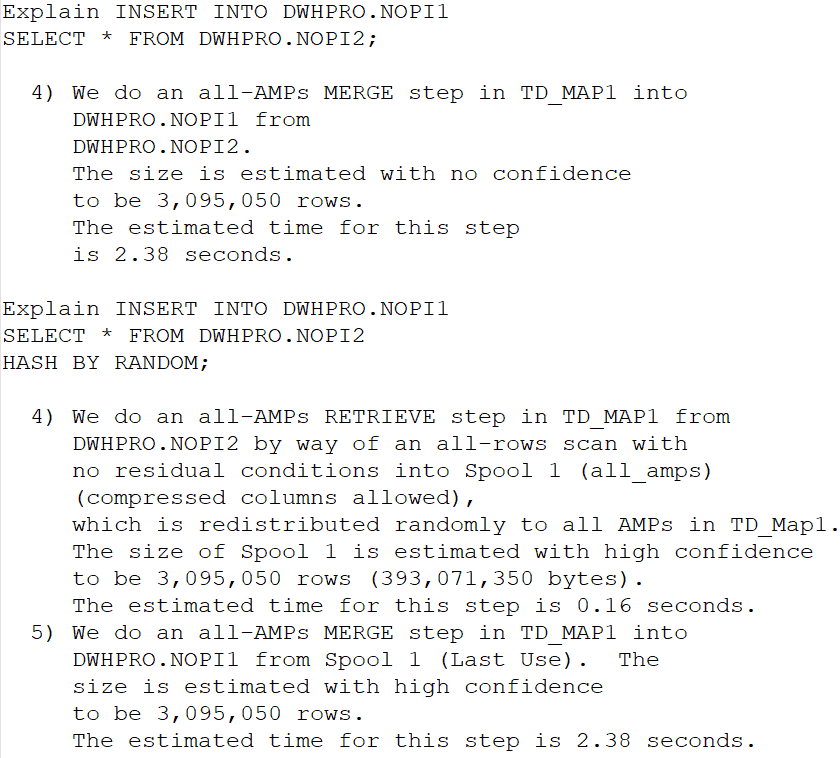
NOPI tables can speed up loading times when utilizing bulk load utilities. Nevertheless, transactional INSERT INTO statements into NOPI tables may result in skewed data as rows are allocated to AMPs locally, potentially causing the “no more spool space” problem. A suitable INSERT … SELECT can use HASH BY RANDOM to redistribute rows. The plan below illustrates random redistribution; it does not guarantee exactly equal row counts on every AMP.
Why do I have a “no more spool space” problem after a Teradata upgrade, although the query worked before?
SELECT MAX(Vproc) AS HighestVproc
FROM DBC.TableSizeV;
What are Phantom Spool and Leftover Spool?
For Phantom Spool, the table DBC.DatabaseSpace shows that the spool is in use, but Teradata occupies no space on the disk. The leftover spool is the Teradata spool space that remains after a request has ended.
How can Phantom Spool Space be released?
A DBA can use SYSLIB.FixCurrentSpace to correct space-accounting inconsistencies after confirming that the issue is phantom spool rather than active query usage.
Do not use the earlier all-databases spool example on this page: some releases reject it with “Spool or Persistent Spool option cannot be specified for all databases.” Ask your DBA to check the supported arguments and target user for your release in the FixCurrentSpace documentation before running a repair.
A space-accounting repair does not fix query skew, inefficient plans, or a genuinely exhausted spool allocation.
Types of Teradata Spool Space
- Intermediate: It will be released as soon as it is no longer needed. Intermediate Spool Space is required by derived subqueries, for example. The execution plan provides information about when spool space is released.
- Output: The Output Spool Space holds the result of an SQL request.
- Volatile: Teradata uses volatile spool space for volatile tables.
- Persistent: Persistent Spool Space is used for critical workloads and survives a system restart or a node crash. We can define the critical workload per session or the whole system.
Solve The Teradata Spool Space Problem – Failure 2646 No more spool space
As previously stated, “no more spool space” can be caused by various circumstances. Here are some suggestions for preventing this issue:
Ensure up-to-date statistics
Up-to-date statistics are crucial for the optimizer to avoid excessive data transfer between AMPs.
Choose a good Primary Index.
Select a primary index for your tables that evenly distributes the rows among all AMPs.Prevent “no more spool space” on the system level
Avoid spool space depletion by implementing a spool reserve database.
Release Spool Space as soon as possible
Immediately drop volatile tables when they are no longer necessary to avoid unnecessary blockage of spool space and cylinders that Teradata could use as permanent space. Though it is expected to happen automatically at the end of the session, relying on this is not advisable.
Use Multivalue Compression
Multivalue compression can reduce the storage needed for eligible repeated values. Its effect on spool depends on the data, plan and intermediate row representation. Measure the relevant query before treating compression as a spool-space fix.
Use the appropriate data types
Choose types that cover the required domain without unnecessarily wide rows. BYTEINT has a smaller value payload than INTEGER, but total spool also includes other columns and row overhead. VARCHAR adds length overhead and is not always smaller than CHAR. Reduce unnecessary projected columns and measure the actual intermediate row sizes.
Primary Index Access instead of Full Table Scans
Selective access paths and partition elimination can reduce rows read or passed to later steps. They do not guarantee a spool-free query: joins, sorts, aggregation and result handling may still need spool. Choose indexes and partitioning for the measured workload rather than avoiding every full-table scan.
Use the DATABLOCKSIZE parameter to create smaller data blocks
DATABLOCKSIZE is a physical-design setting, not a general remedy for error 2646. Changing it can affect I/O and other workloads. Investigate query row counts, skew and limits first; test any physical-design change with representative workloads.
Use columnar table design
Columnar tables can significantly reduce required spool space when the access pattern is appropriate, as only necessary columns are spooled. However, precise analysis and adaptation to the workload are necessary when utilizing columnar tables. A comparable outcome can be obtained by vertically partitioning tables and decreasing the number of columns.
To prevent acute space issues resulting from skew, Teradata offers new features that can efficiently manage permanent space:
Here is a link to the Teradata Spool space documentation:https://docs.teradata.com/reader/ueCMQAxljdET5klb6rbF1g/1Ui60fKd7ae50Aggfgl57A
The join method is often what fills the spool in the first place: why a product join explodes where a merge join does not.
For the broader set of habits that keep spool usage down: the tuning checks worth running first.
Skew is the other common cause of a full spool: how skew builds up and how to see it and the wider tuning checklist.
For general habits: the everyday tuning checks.
For related examples, see volatile-table commit behaviour and the spool implications of CREATE TABLE AS.
Reproduce the lab checks
Download the SQL used for these functional checks. Run it in a separate BTET lab session with unused dwhpro_ai_* table names. It creates and drops only its own volatile tables and reads DBC metadata; it contains no login credentials. Execute the statements separately, as in the test. The file covers date formatting, duplicate rows, commit behaviour, table copying and spool counters.
Distinguish skew, concurrent usage and a spool limit
Why can a query fail when total spool usage is low?
A total hides where the bytes are used. One AMP can reach its effective limit while others have room. It can also hide when the bytes were used: a sample after failure can be lower because temporary spool has been released. In the lab example above, the constant-key insert failed while the distributed-key insert completed under the same allocation.
How do I distinguish skew from concurrent-session consumption?
Capture per-AMP counters during the failing request, together with the active requests for that account. A concentrated rise suggests a distribution problem; concurrent requests can consume the same user allocation even when each succeeds alone. Both can occur together. Account-level DiskSpaceV rows alone cannot attribute consumption to one session. Correlate them with authorized Viewpoint or DBQL evidence and the relevant plan step.
What should I record before increasing the allocation?
- The request identifier, timestamp, user/profile and relevant logging coverage.
- Effective spool settings, AMP topology and applicable skew/space policies.
- EXPLAIN estimates versus actual step rows and resource counters, where collected.
- Concurrent requests and retained volatile data.
- Whether the same query succeeds with comparable input in an isolated lab.
Increase a limit only after distinguishing configuration from row multiplication, skew and physical capacity. A larger allocation can postpone a failure without fixing its cause. See DBQL evidence and its coverage limits and skew investigation.
Need help with query performance or platform costs?
Diagnose plans, skew, spool pressure and expensive workloads. Agree a baseline and acceptance criteria before making changes.
Get the complete Teradata tuning book, free
Teradata Query Performance Tuning: The DWHPro Guide
By Roland Wenzlofsky & Artemios Vogiatzis
206 pages on statistics and demographics, access paths and indexes, query execution plans, and joins. Get the full PDF and practical Teradata updates from DWHPro.
Confirm your email to receive your download link. Privacy policy. Unsubscribe in any newsletter.
About the free book
If you don’t have access to remote console utility and dont have access to primary node then how we can release the phantom spool space ?
Correction — 24 October 2026: The all-databases spool repair example in this 2020 reply is withdrawn. Some releases reject it with “Spool or Persistent Spool option cannot be specified for all databases.” A DBA must confirm a space-accounting inconsistency, check the supported arguments for the installed release and target the affected user. This procedure does not fix query skew or genuinely exhausted spool. See the current FixCurrentSpace reference and the updated article above. The original reply below is retained for context, not as an instruction to execute.
You can try:
call SYSLIB.FixCurrentSpace(‘S’, ‘Y’, ‘N’, null, cnt, err);
Details are here:
FixCurrentSpace
Thanks for the question. I have included it in the article because I think it might be interesting for others as well.
I get this error in the errorinfo column when I run the stored procedure. Do you know why this occurs ?
CALL SYSLIB.FixCurrentSpace(‘S’, ‘Y’, ‘N’, NULL, Cnt, err);
Spool or Persistent Spool option cannot be specified for all databases.