Teradata Load Times vs. Snowflake Load Times
Elasticity is a crucial aspect of contemporary cloud databases like Snowflake that sets them apart from on-premise shared-nothing databases like Teradata.
The lower cost (“pay only what you need”) is one of the main advantages. I think this is a very one-sided approach. Databases like Snowflake must first prove how they compare to Teradata regarding many parallel queries, and Snowflake has to be scaled up accordingly.
Selecting a winner is a complex task as it relies heavily on the workload. Broad statements can be made to support this notion.
Doubling compute does not guarantee halving ETL runtime or preserving cost. Snowflake warehouse billing is per second with applicable minimums; startup, resizing, concurrency and service costs matter. This article supplies no controlled comparative benchmark.
I will demonstrate why accelerating the ETL process with Teradata is challenging. However, it should be noted that the assertion is not that Snowflake has a lesser total cost of ownership.

Get the complete Teradata tuning book, free
Teradata Query Performance Tuning: The DWHPro Guide
By Roland Wenzlofsky & Artemios Vogiatzis
206 pages on statistics and demographics, access paths and indexes, query execution plans, and joins. Get the full PDF and practical Teradata updates from DWHPro.
Confirm your email to receive your download link. Privacy policy. Unsubscribe in any newsletter.
About the free bookTeradata VantageCloud Lake offers independent compute clusters and object storage. Compare that deployment separately from a traditional on-premises system; the former blanket cloud-scaling limitation is outdated.
The ETL Process
Consider a typical ETL process that involves reading data from a source, transforming it, potentially historizing it, and ultimately writing it to the target database.
Some ETL jobs/scripts have dependencies, but others can be executed concurrently since they lack dependencies.
What is the typical arrangement nowadays? Multiple ETL scripts are executed concurrently in a batch on either an ETL server or a cluster of servers.
Sizing The Compute Node Cluster in Snowflake
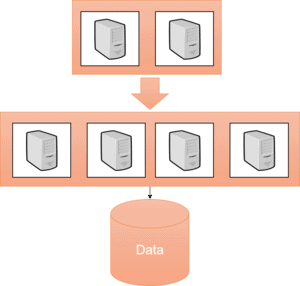
Increasing a Snowflake warehouse size is one candidate to test, not a cost-neutral acceleration guarantee. Measure runtime and billed consumption for the complete ETL workload before choosing a size.
This model’s success depends on the method of charging for cloud resource utilization.
Although we may not have a cost advantage, we have the ability to control our loading process within Snowflake flexibly.
Adding Additional Compute Node Clusters in Snowflake
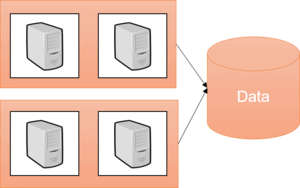
An alternative option is to execute the scripts on several autonomous clusters.
Independent warehouses can reduce resource contention but do not remove data dependencies, transaction constraints or other bottlenecks. Measure the complete ETL dependency graph.
Each cluster’s jobs can now utilize its dedicated resources.
It is crucial to remember that jobs in a cluster compete for CPU, memory, and IO resources.
Why Teradata Is Not Suitable
Initiating additional compute nodes incurs expenses. Due to its ability to accomplish this in minutes, Snowflake is exceptionally adept at adapting to fluctuating workloads.
As previously stated, this does not address the overall ownership expenses, and I believe costs cannot be universally defined.
Snowflake’s marketing is deceptive because it claims to have a significantly lower total cost of ownership (TCO) than Teradata.
On the contrary, Teradata asserts that Snowflake requires numerous additional compute nodes to achieve optimal performance in the parallel execution of many competing requests.
Both of their marketing strategies are flawed, as the final outcome is contingent on the amount of work involved.
For further information, kindly visit the Snowflake official website:
Planning a Teradata-to-Snowflake migration?
Review the assessment, conversion, reconciliation and cutover work needed for a controlled transition.
Get the complete Teradata tuning book, free
Teradata Query Performance Tuning: The DWHPro Guide
By Roland Wenzlofsky & Artemios Vogiatzis
206 pages on statistics and demographics, access paths and indexes, query execution plans, and joins. Get the full PDF and practical Teradata updates from DWHPro.
Confirm your email to receive your download link. Privacy policy. Unsubscribe in any newsletter.
About the free book