How does Teradata handle Skew in Joins?
The imbalanced workload is a primary issue that must be addressed in performance optimization.
Part of the Teradata Physical Design and Data Modelling guide.
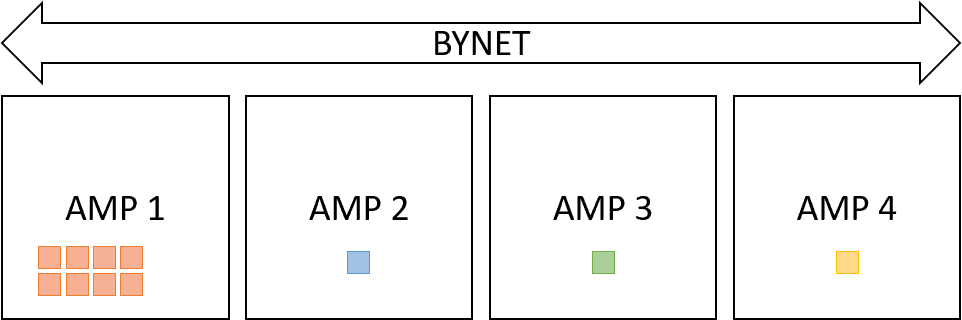
Efficient optimization is crucial for join steps due to the possibility of Teradata transferring significant data volumes between AMPs.
The optimizer can perform joins separately for primary index values that are skewed and those that are not. It then duplicates the skewed values across all AMPs and redistributes the unskewed values.
This technique is called Partial Redistribution and Partial Duplication, or PRPD for short. You can read more about it here:
This article demonstrates how the optimizer adjusts the join strategy, including the join method and join geography, in the event of skew, assuming that relevant statistics are accessible. Specifically, we will examine a merge join as an example.
Our example uses two tables, each with “PK” as the primary index.
The left table is joined on “col6”, which is not the primary index.
Calculating the rowhash for “col6” is necessary at some point during the join plan to execute a merge join.
Statistics on join columns have been gathered to inform the optimizer of skew. Biased values within skewed columns are represented in the statistics histograms and factored into creating the join plan.

Get the complete Teradata tuning book, free
Teradata Query Performance Tuning: The DWHPro Guide
By Roland Wenzlofsky & Artemios Vogiatzis
206 pages on statistics and demographics, access paths and indexes, query execution plans, and joins. Get the full PDF and practical Teradata updates from DWHPro.
Confirm your email to receive your download link. Privacy policy. Unsubscribe in any newsletter.
About the free bookThe table on the left contains six million rows, while the one on the right has 500,000.
We run the query below:
SELECT *
FROM
  TEST_DB.left_table main
INNER JOIN
   TEST_DB.TABLE2 right_table
ON
   main.COL6 = right_table.PK
WHERE
   right_table.COL4 = 'A';
Initially, we evenly distributed data onto both tables across all AMPs. Below is the execution plan crafted by the optimizer, with identified keywords:
4) We do an all-AMPs RETRIEVE step from TEST_DB.main by way of an
all-rows scan with no residual conditions into Spool 2 (all_amps),
which is redistributed by the hash code of (TEST_DB.main.COL6)
to all AMPs.  Then we do a SORT to order Spool 2 by row hash.  The
size of Spool 2 is estimated with high confidence to be 6,708,141
rows (7,184,419,011 bytes).  The estimated time for this step is 1
minute and 46 seconds.
5) We do an all-AMPs JOIN step from TEST_DB.right_table by way of a
RowHash match scan with a condition of ("TEST_DB.right_table.COL4 = 'A
'"), which is joined to Spool 2 (Last Use) by way of a RowHash
match scan.  TEST_DB.right_table and Spool 2 are joined using a merge
join, with a join condition of ("COL6 = TEST_DB.right_table.PK").  The
result goes into Spool 1 (group_amps), which is built locally on
the AMPs.  The size of Spool 1 is estimated with low confidence to
be 6,708,141 rows (28,422,393,417 bytes).  The estimated time for
this step is 31.20 seconds.
The optimizer distributes the left table’s 6 million rows to all AMPs based on the rowhash of the “col6” column.
The first displayed plan redistributes the left input into Spool 2 and joins the filtered right base table directly. It avoids a separate right-side preparation spool, not all spool usage.
Deliberately Skewing the Data
The relevant skew is in left_table.COL6, which joins to right_table.PK. Changing a non-primary-index column does not itself change base-table AMP placement; join-key redistribution can nevertheless concentrate work.
The second historical plan duplicates the entire filtered right input. It illustrates duplication as a skew response, but does not demonstrate a PRPD split between biased and nonbiased values.
4) We execute the following steps in parallel.
1) We do an all-AMPs RETRIEVE step from TEST_DB.right_table by way
of an all-rows scan with a condition of (
"TEST_DB.right_table.COL4 = 'A '") into Spool 2 (all_amps), which
is duplicated on all AMPs.  Then we do a SORT to order Spool
Two by the hash code of (TEST_DB.right_table.PK).  The size of
Spool 2 is estimated with high confidence to be 3,600,000
rows (3,855,600,000 bytes).  The estimated time for this step
is 34.56 seconds.
2) We do an all-AMPs RETRIEVE step from TEST_DB.main by way
of an all-rows scan with no residual conditions into Spool 3
(all_amps), which is built locally on the AMPs.  Then we do a
SORT to order Spool 3 by the hash code of (
TEST_DB.main.COL6).  The size of Spool 3 is estimated with
high confidence to be 6,708,141 rows (7,184,419,011 bytes).
The estimated time for this step is 45.73 seconds.
5) We do an all-AMPs JOIN step from Spool 2 (Last Use) by way of a
RowHash match scan, which is joined to Spool 3 (Last Use) by way
of a RowHash match scan.  Spool 2 and Spool 3 are joined using a
merge join, with a join condition of ("COL6 = PK").  The result
goes into Spool 1 (group_amps), which is built locally on the AMPs.
The result spool file will not be cached in memory.  The size of
Spool 1 is estimated with low confidence to be 3,354,070,500 rows
(14,211,196,708,500 bytes).  The estimated time for this step is 3
hours and 26 minutes.
The statistics histogram segregates the frequently occurring values as “biased values,” which the optimizer utilizes for join planning.
The optimizer may choose to join the table separately for skewed and non-skewed values and then merge the resulting sets for an overall result.
Regardless of the join strategy utilized by the optimizer:
Collect and validate useful join-column statistics, especially for skewed values. Sampled statistics can be adequate when they capture the distribution; full collection is not a universal prerequisite. Compare estimates with actual cardinality.
Need help with query performance or platform costs?
Diagnose plans, skew, spool pressure and expensive workloads. Agree a baseline and acceptance criteria before making changes.
Get the complete Teradata tuning book, free
Teradata Query Performance Tuning: The DWHPro Guide
By Roland Wenzlofsky & Artemios Vogiatzis
206 pages on statistics and demographics, access paths and indexes, query execution plans, and joins. Get the full PDF and practical Teradata updates from DWHPro.
Confirm your email to receive your download link. Privacy policy. Unsubscribe in any newsletter.
About the free book